Best AI for posters with Chinese text
GPT Image 2.5 is our pick, with a BiBi Score of 87. Our blind panel rated it, Seedream 5.0 Pro and Nano Banana 2.1 best on looks, with gaps too small to call a winner, and all three got every one of 58 Chinese characters right. What decides it is price: 0.5 credits per usable poster against 1.25 and 1.5. If cost doesn't matter to you, any of the three will do. Recraft V4.1 came clearly last on looks.
BiBi Scores
One attempt per model per poster, no retries, no cherry-picking. Looks are graded blind; reliability is whether every word on the poster is right.
| # | Model | BiBi Score | Looks (blind panel) | Reliability | Value |
|---|---|---|---|---|---|
| 1 | GPT Image 2.5 | 76range 70–82 · tied with the best | 100 | 1000.5 credits per usable poster | |
| 2 | Seedream 5.0 Pro | 74range 65–82 · tied with the best | 100 | 601.25 credits per usable poster | |
| 3 | Nano Banana 2.1 | 72range 64–79 · tied with the best | 100 | 521.5 credits per usable poster | |
| 4 | Grok Image 2.0 | 67range 59–75 · tied with the best | 100 | 402 credits per usable poster | |
| 5 | FLUX 3 Image | 67range 58–76 · tied with the best | 90 | 352.22 credits per usable poster | |
| 6 | Ideogram 4.5 | 58range 52–63 | 90 | 352.22 credits per usable poster | |
| 7 | Recraft V4.1 | 47range 37–57 | 90 | 561.39 credits per usable poster |
All four graders put the models in nearly the same order (average rank correlation 0.94, lowest pair 0.88). They differed mainly in how generous they were, which we correct for. With 10 posters, Ideogram 4.5 and Recraft V4.1 are clearly behind on looks; the top five are close enough that their ranges overlap.
BiBi Score = looks 50% + reliability 20% + value 20%, rescaled to 100 (ease of use, the other 10%, is not scored while every model runs on the same platform). Looks: four graders scored every output 1–10 without seeing model names; each grader's scores are adjusted for how strict or generous they were, and the range shows where 90% of resamples of graders and briefs land. Reliability: our own pass/fail checks against the brief. Value: cost per usable output; the cheapest model gets 100 and every doubling of cost loses 30. How scoring works.
Text accuracy
A poster counts as usable when every requested word is right and readable.
| Model | Chinese characters right | Posters with every word right | Credits per poster | Credits per usable poster |
|---|---|---|---|---|
| GPT Image 2.5OpenAI · Sunburst, medium quality, 1K | 58 / 58 | 10 / 10 | 0.5 | 0.5 |
| Seedream 5.0 ProByteDance · 1K | 58 / 58 | 10 / 10 | 1.25 | 1.25 |
| Nano Banana 2.1Google · 1K | 58 / 58 | 10 / 10 | 1.5 | 1.5 |
| Grok Image 2.0xAI · medium quality, 1K | 58 / 58 | 10 / 10 | 2 | 2 |
| Recraft V4.1Recraft · standard, 1K | 57 / 58 | 9 / 10 | 1.25 | 1.39 |
| FLUX 3 ImageBlack Forest Labs · 1K | 57 / 58 | 9 / 10 | 2 | 2.22 |
| Ideogram 4.5Ideogram · medium quality, magic prompt off, 1K | 57 / 58 | 9 / 10 | 2 | 2.22 |
| Midjourney V8.1Midjourney | Not on Higgsfield; not tested in this round | |||
| Qwen-Image 3.0Alibaba | API by invitation only; not tested in this round | |||
Credits are what Higgsfield charged at these settings on 31 Oct 2026.
All 70 posters
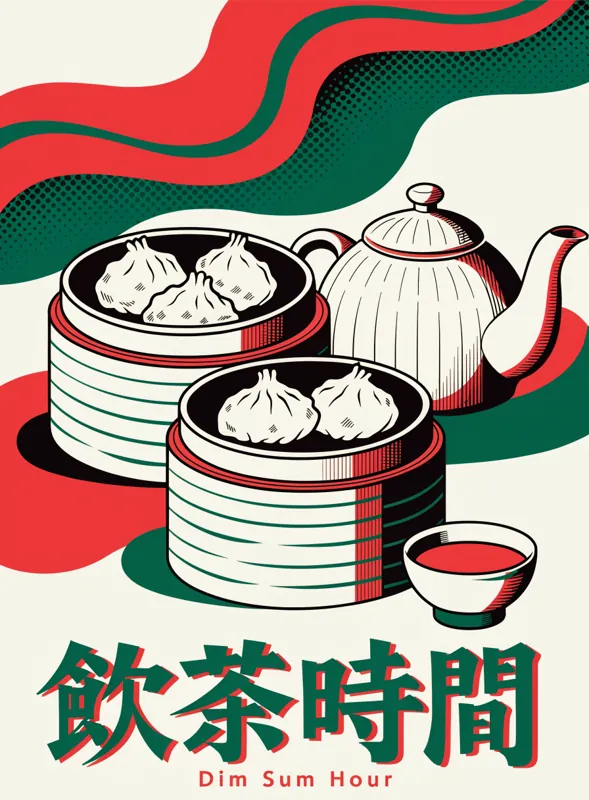
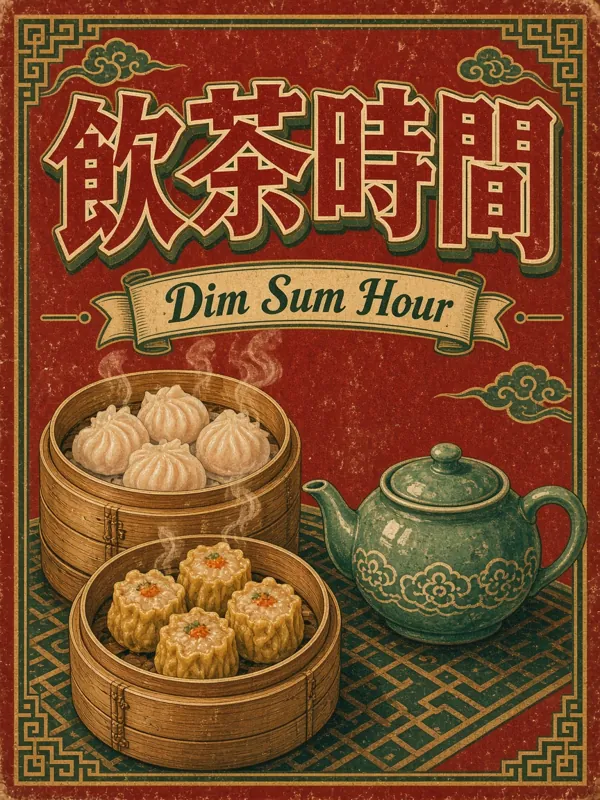
Every output from this round, unedited, in the order the models were run.
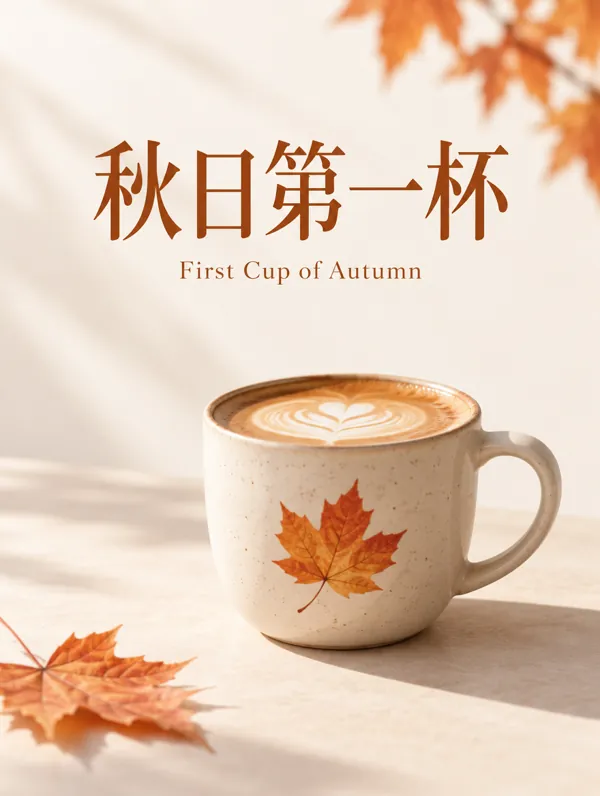
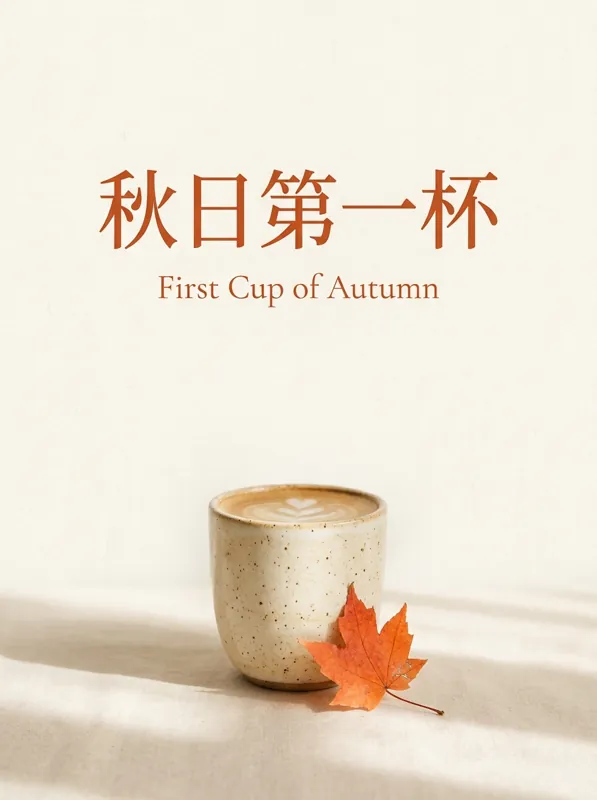
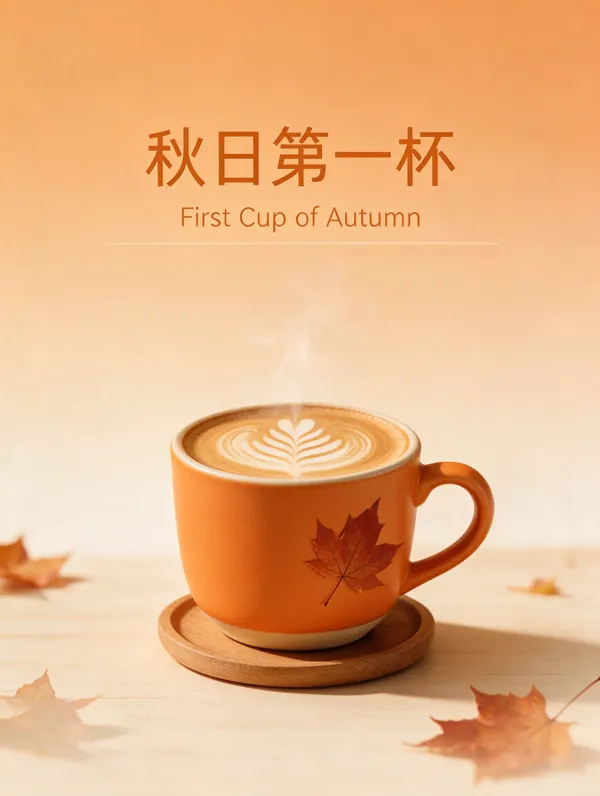
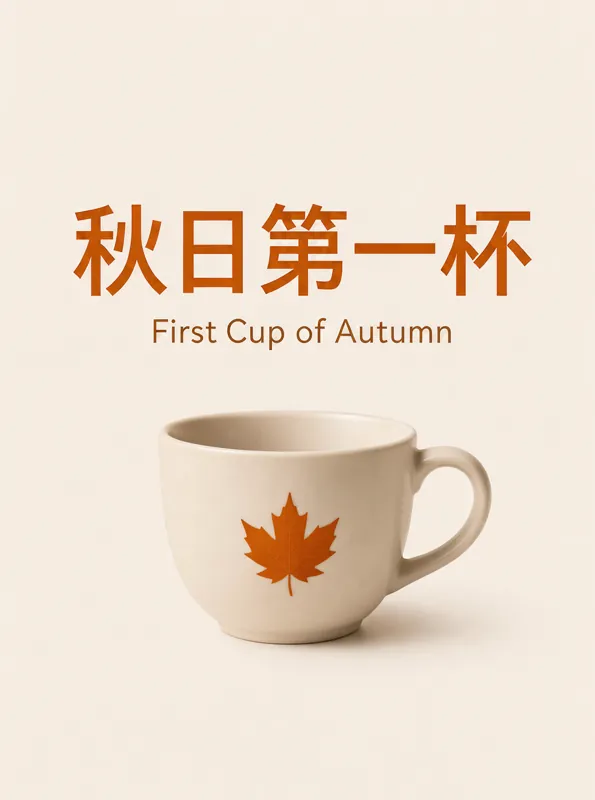
Poster 1: 秋日第一杯 / First Cup of Autumn
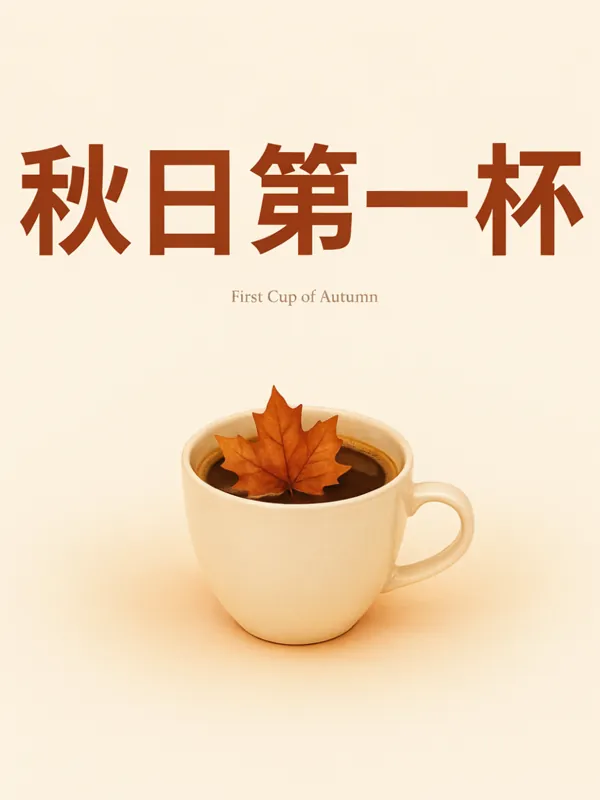
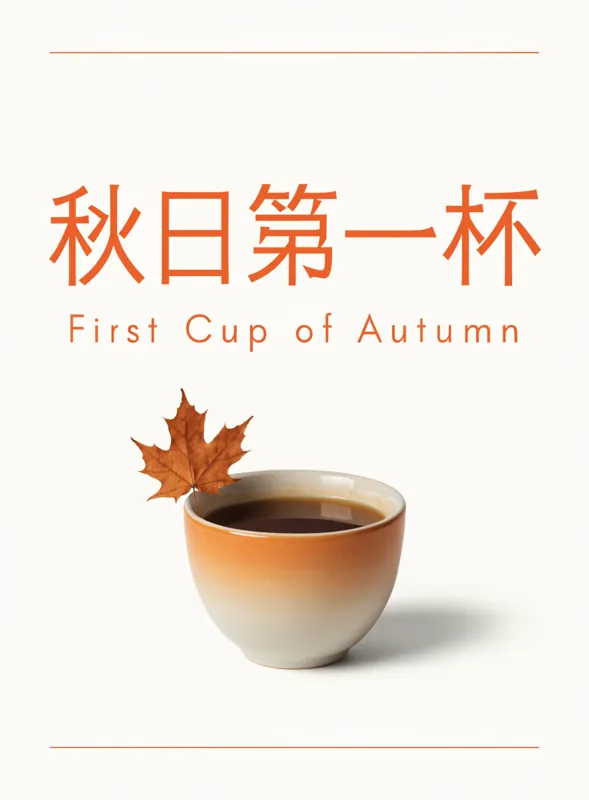
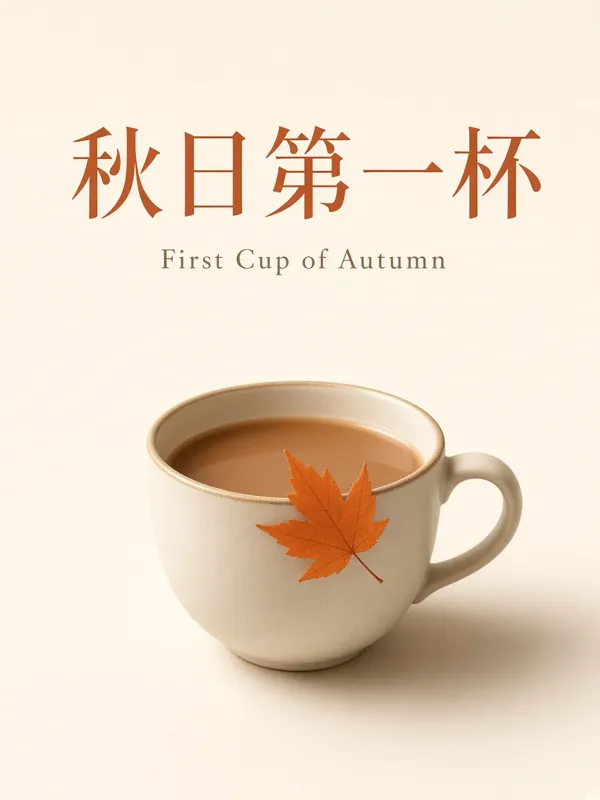
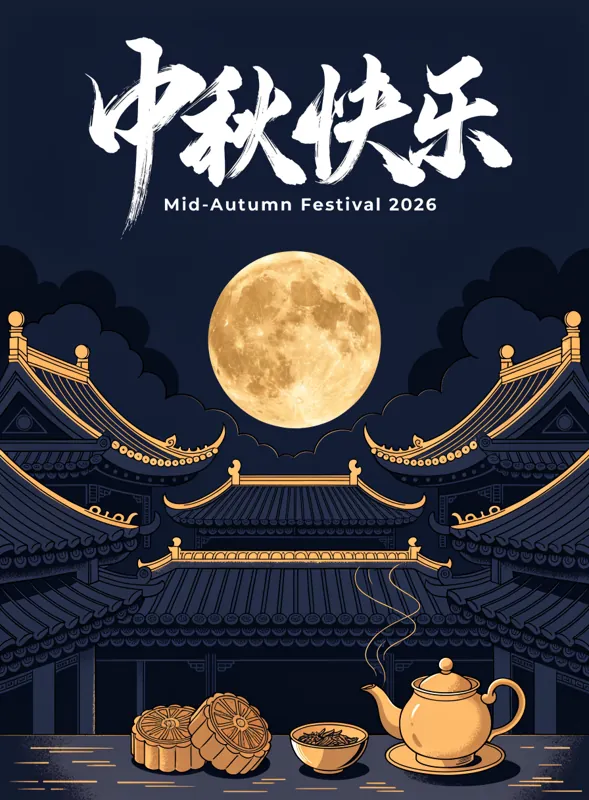
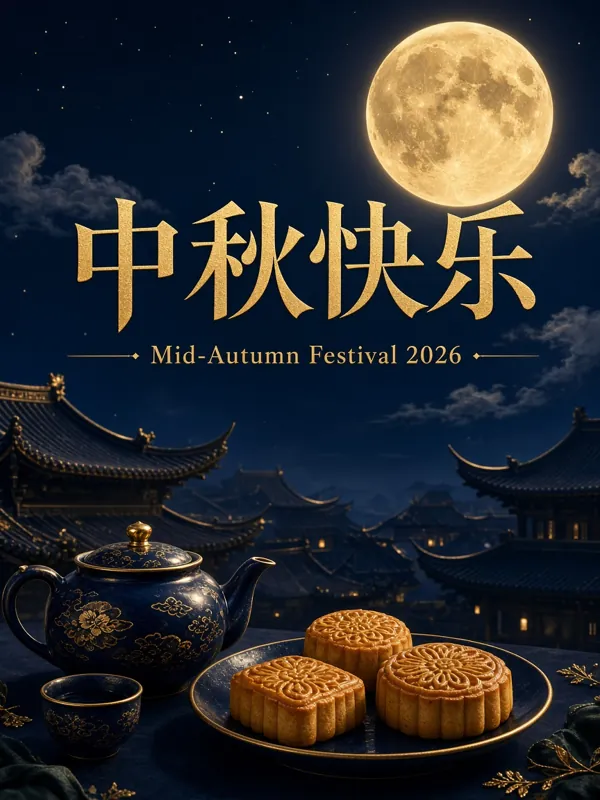
Poster 2: 中秋快乐 / Mid-Autumn Festival 2026
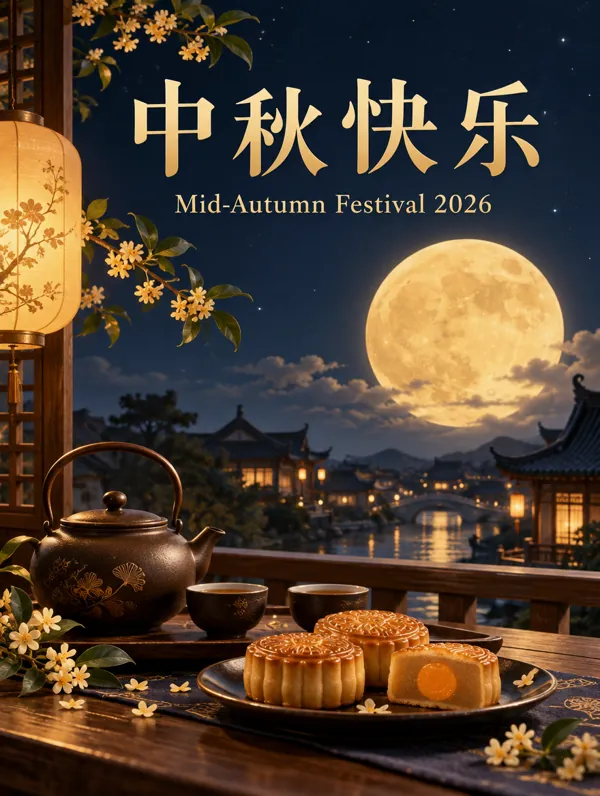
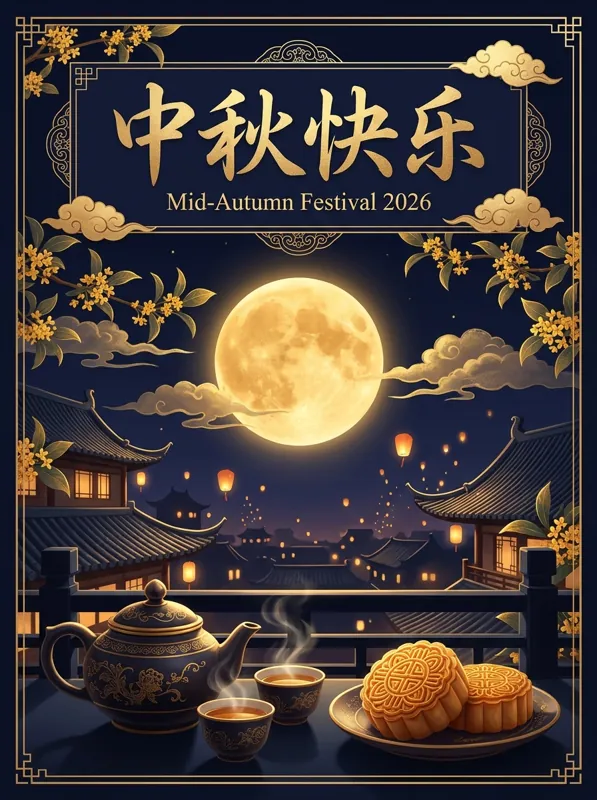
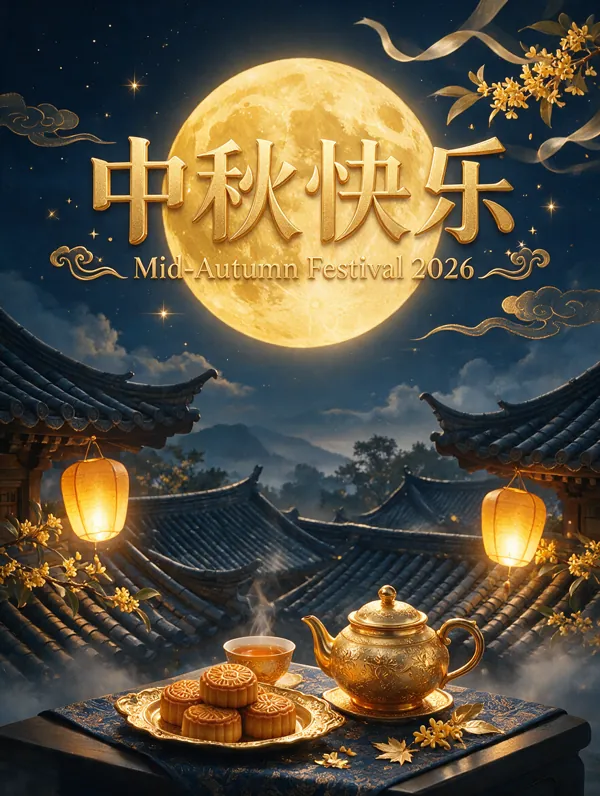
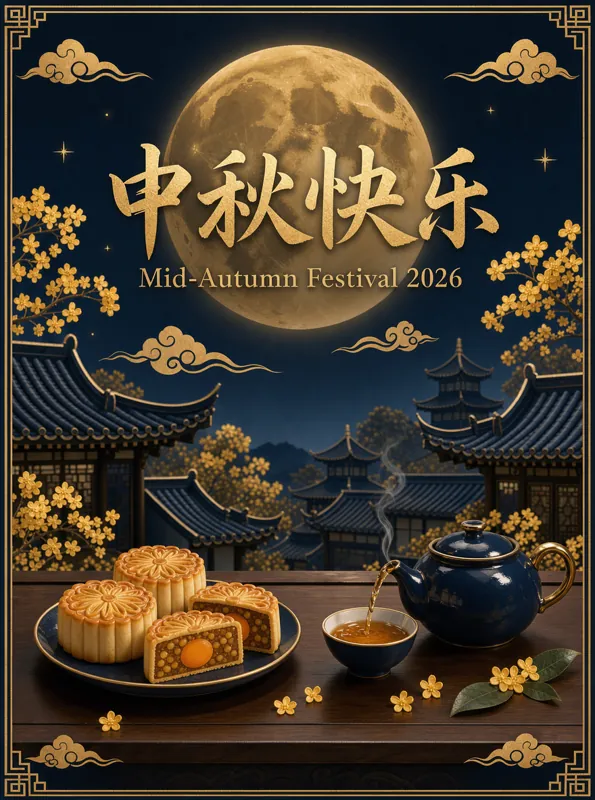
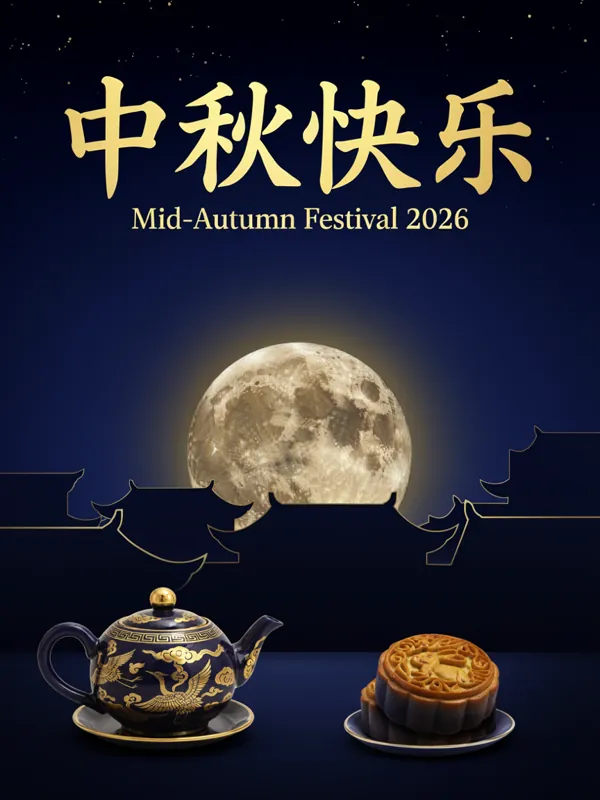
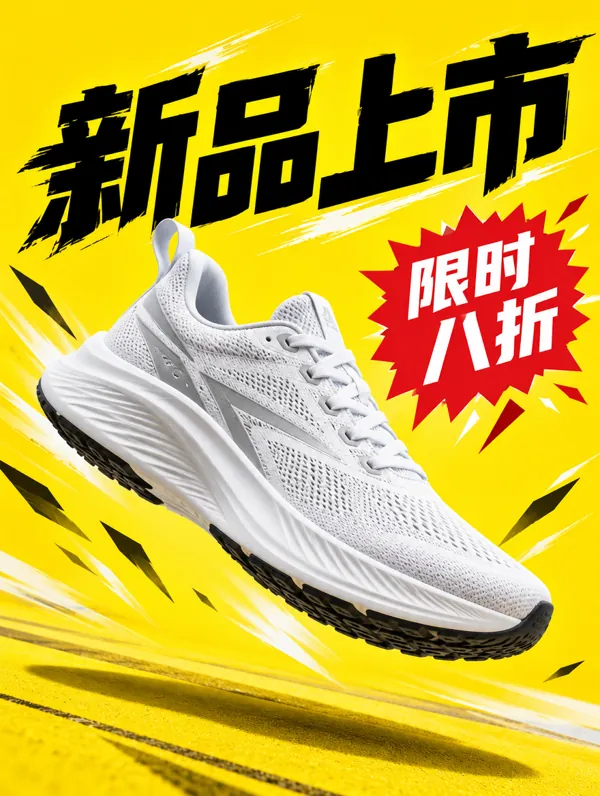
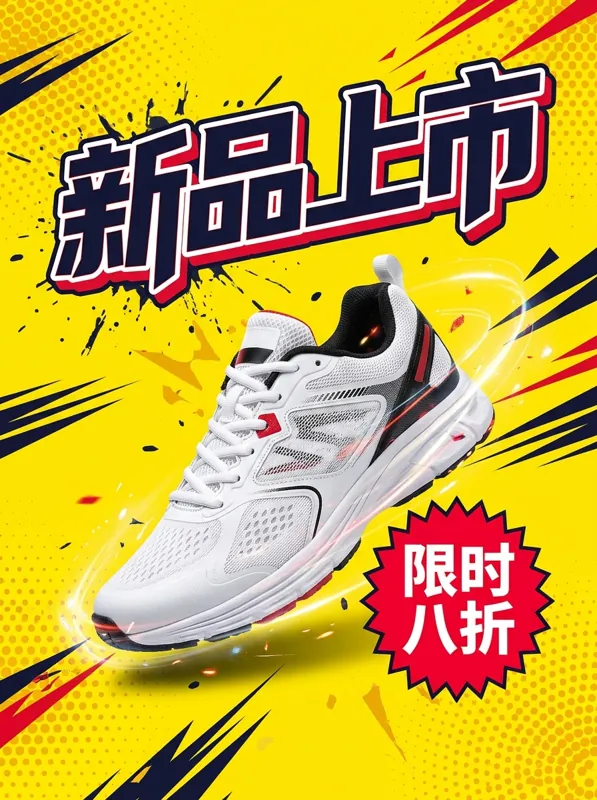
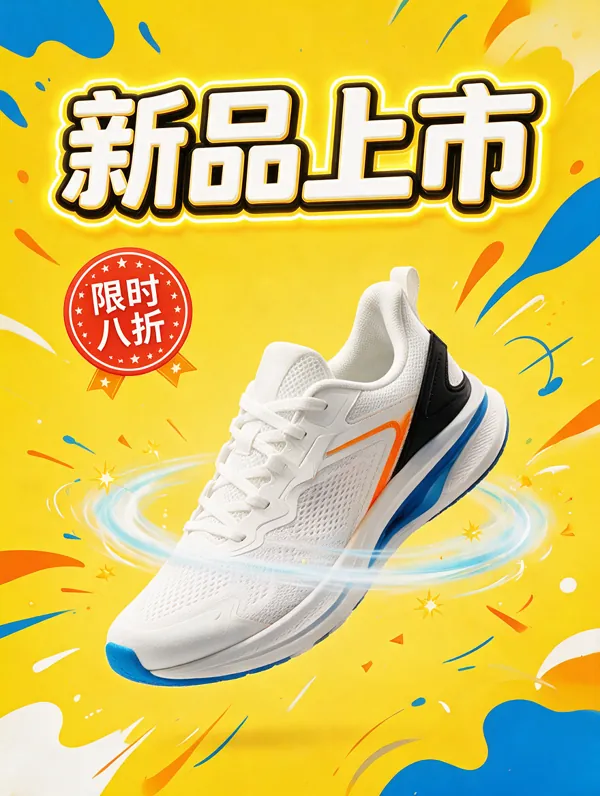
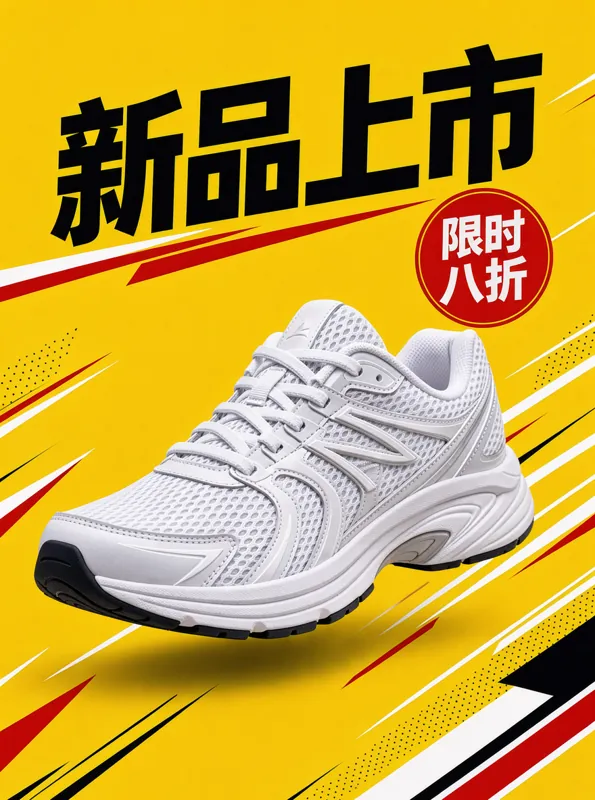
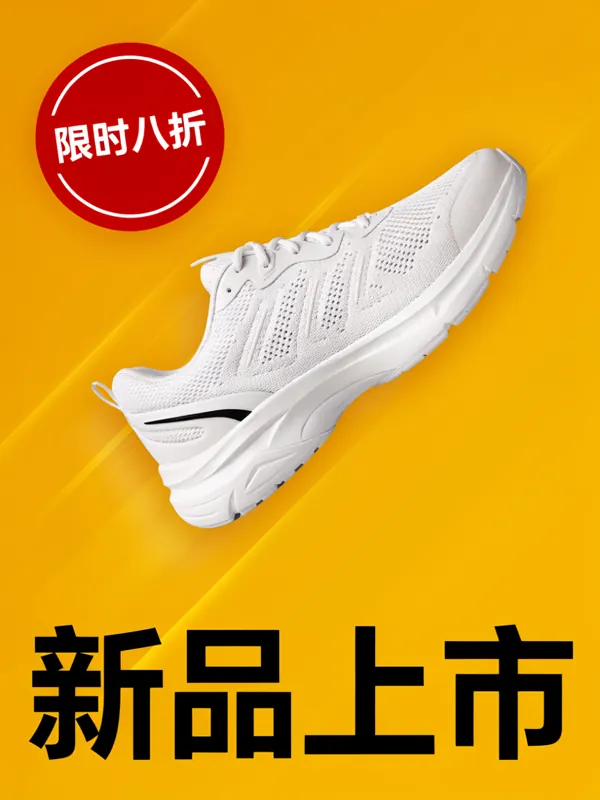
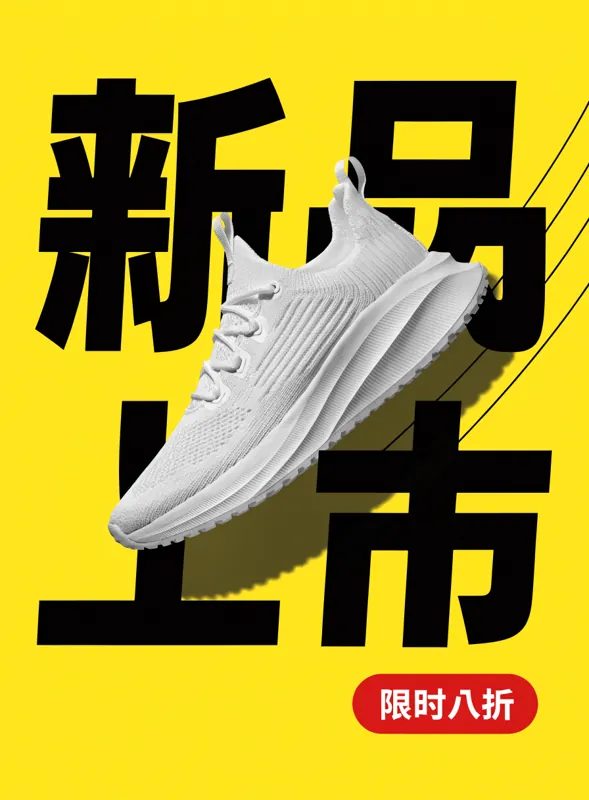
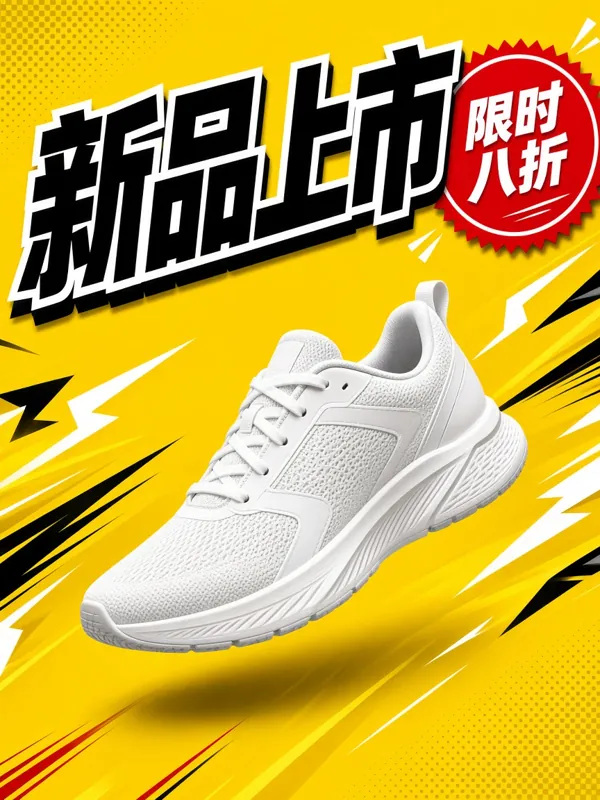
Poster 3: 新品上市 / 限时八折
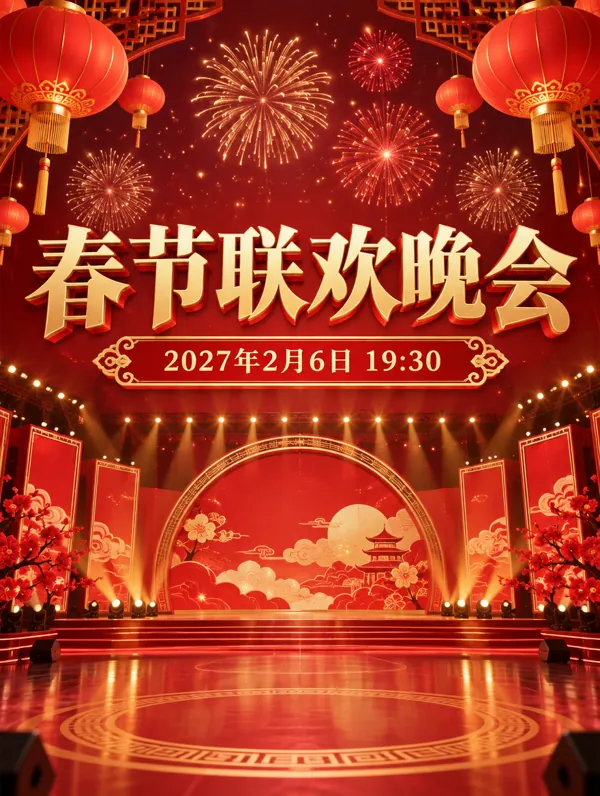
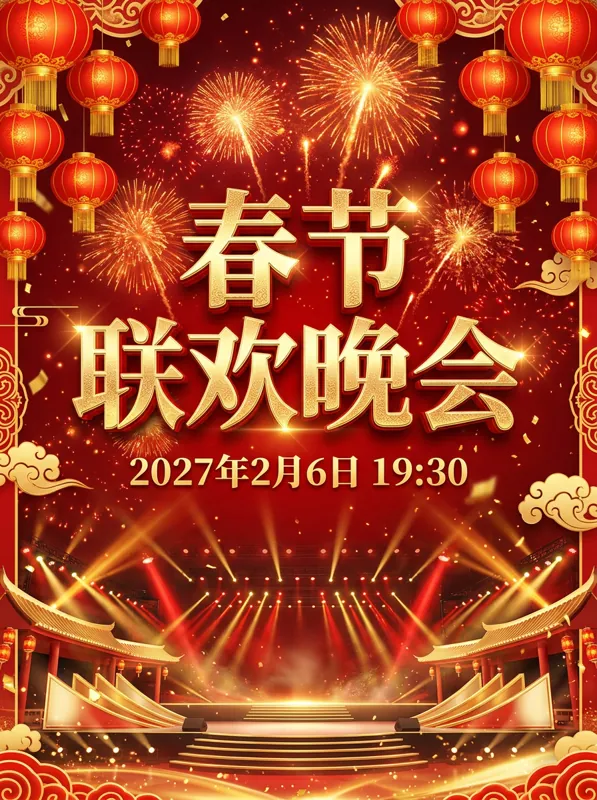
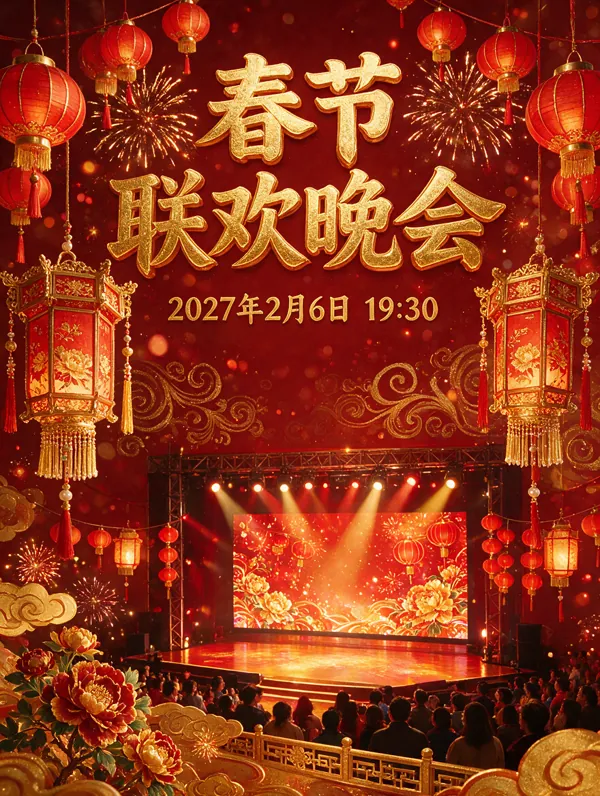
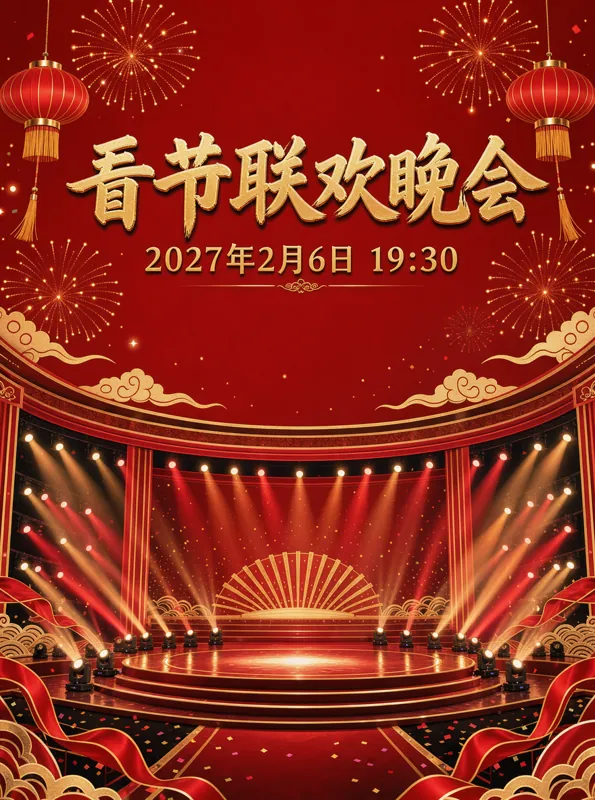
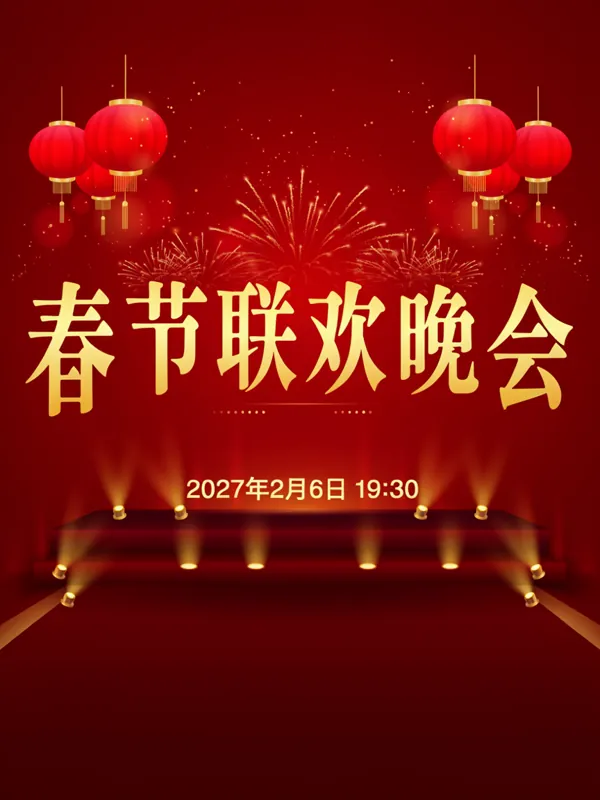
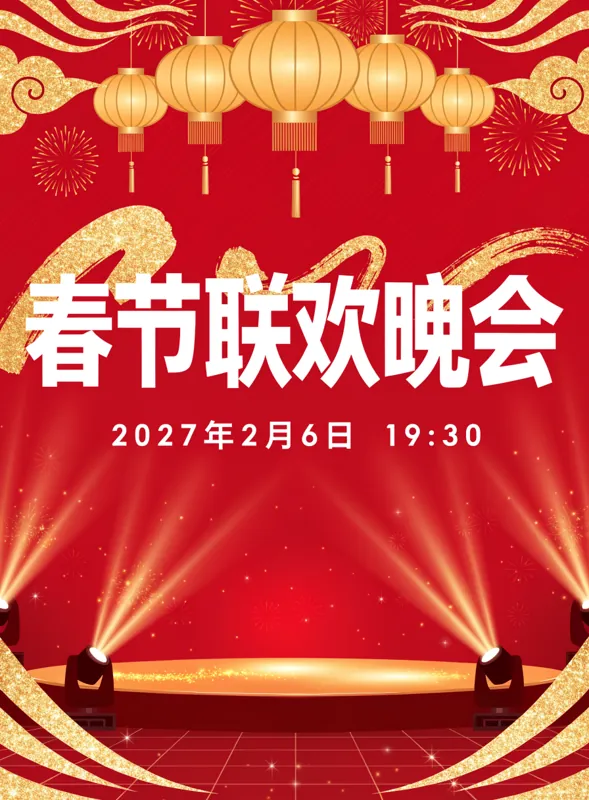
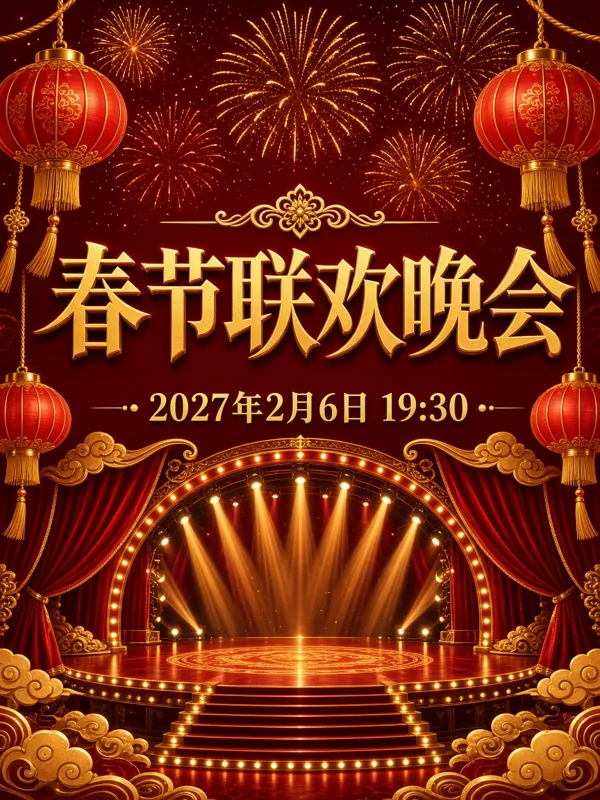
Poster 4: 春节联欢晚会 / 2027年2月6日 19:30
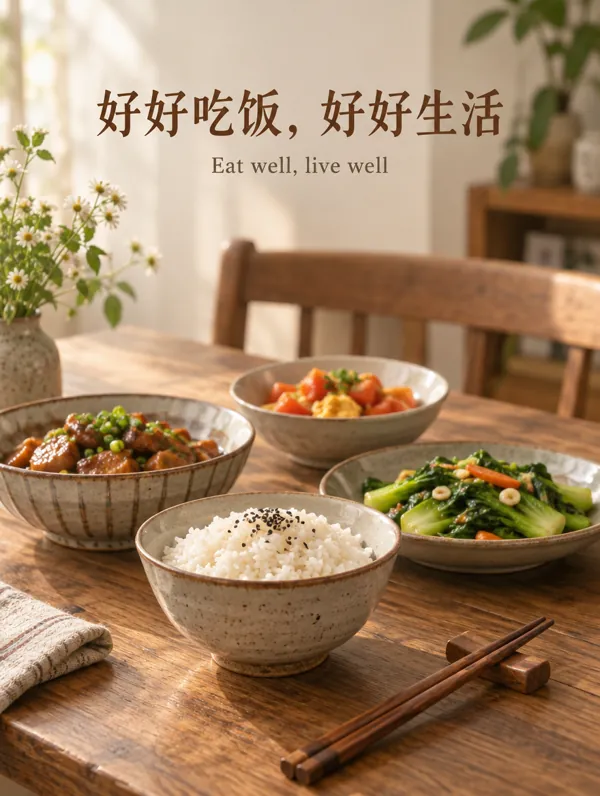
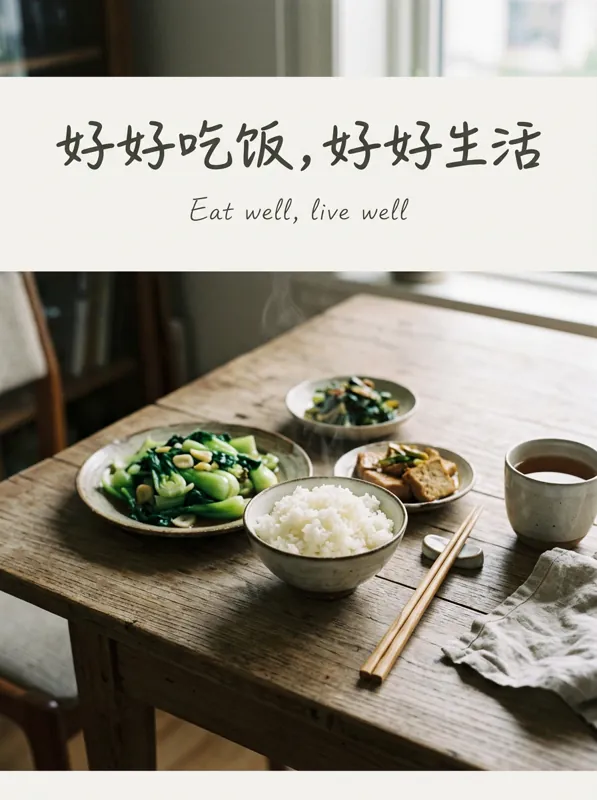
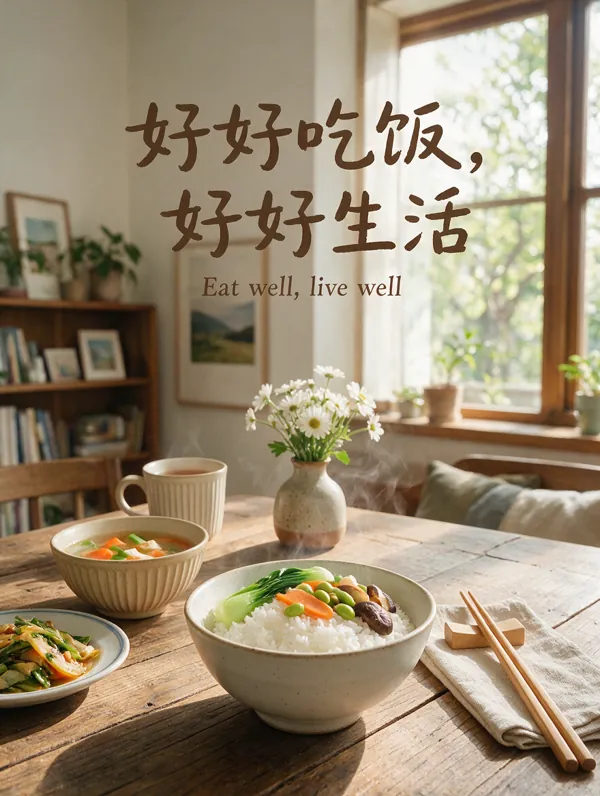
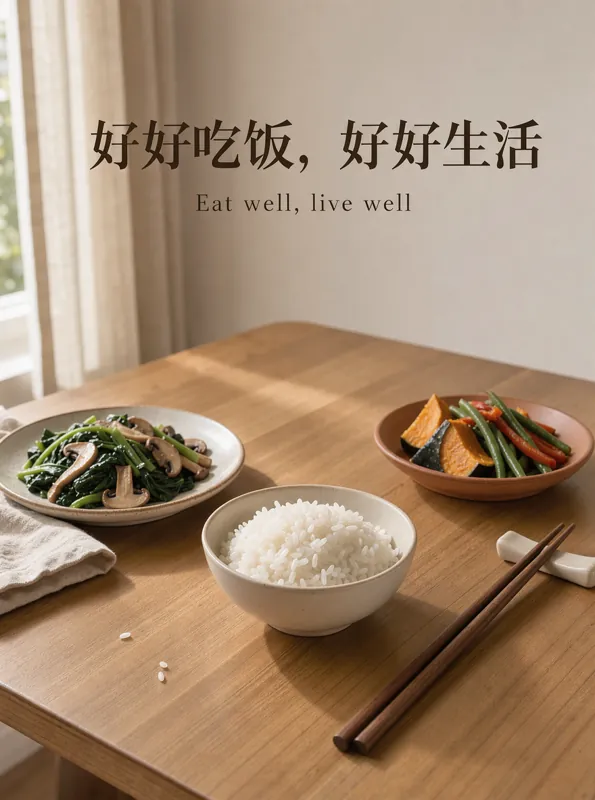
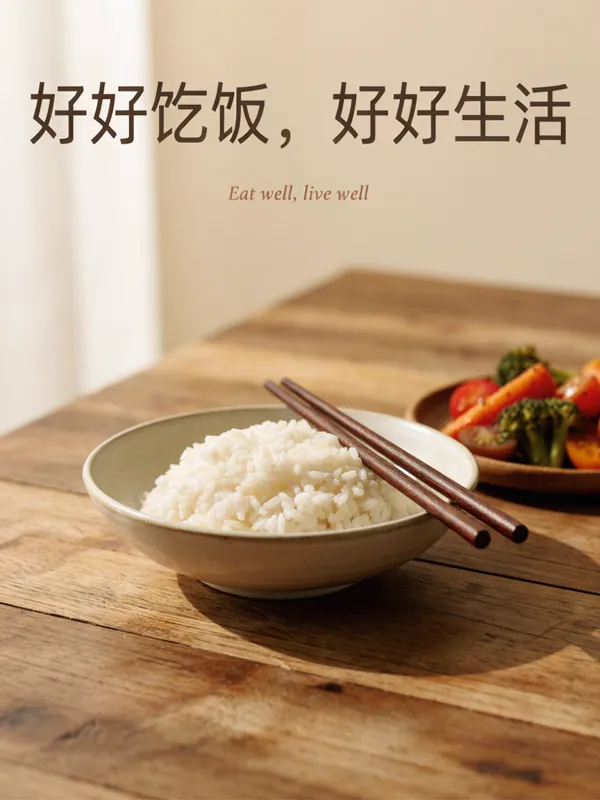
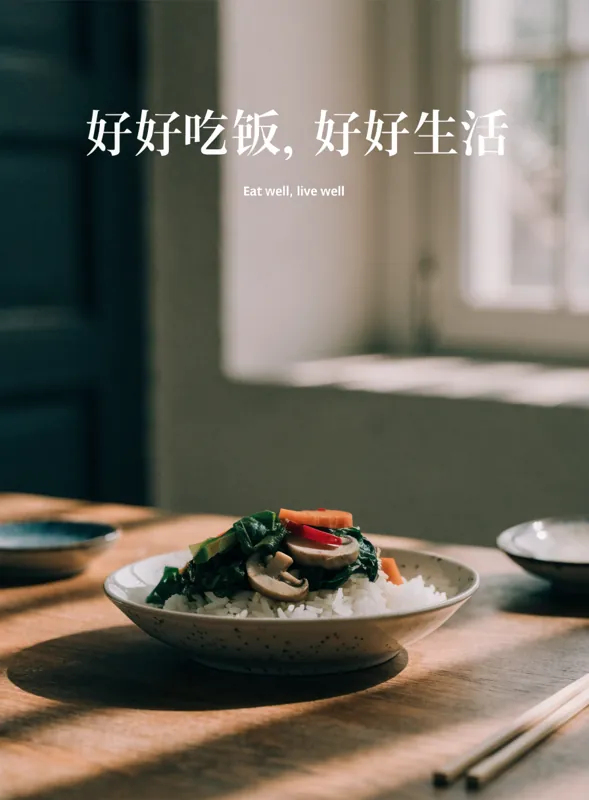
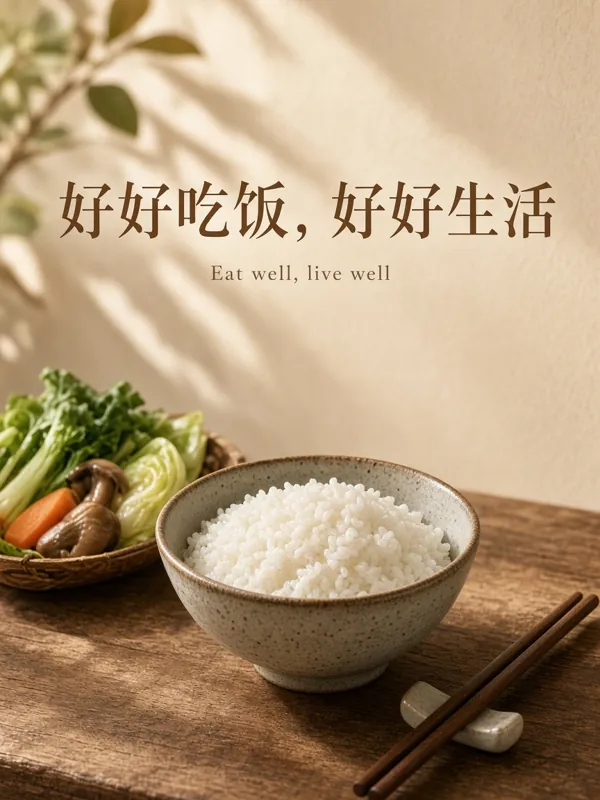
Poster 5: 好好吃饭,好好生活 / Eat well, live well
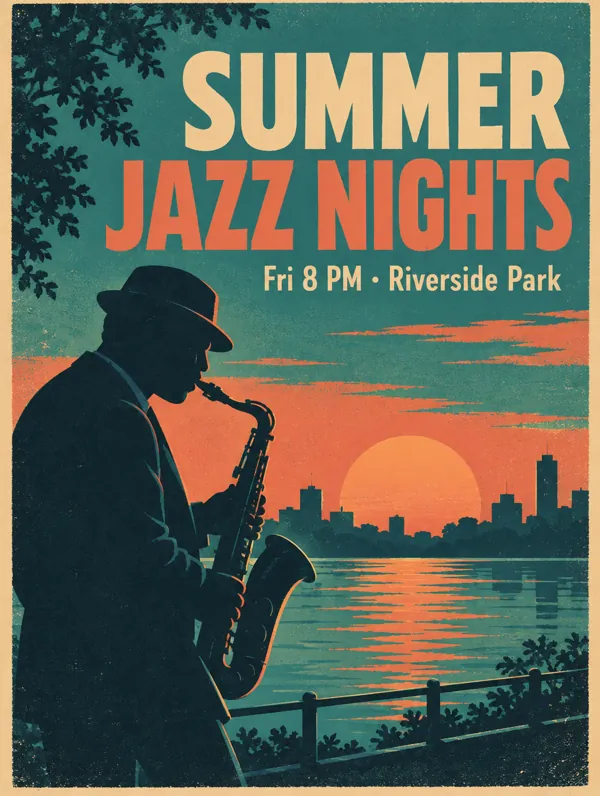
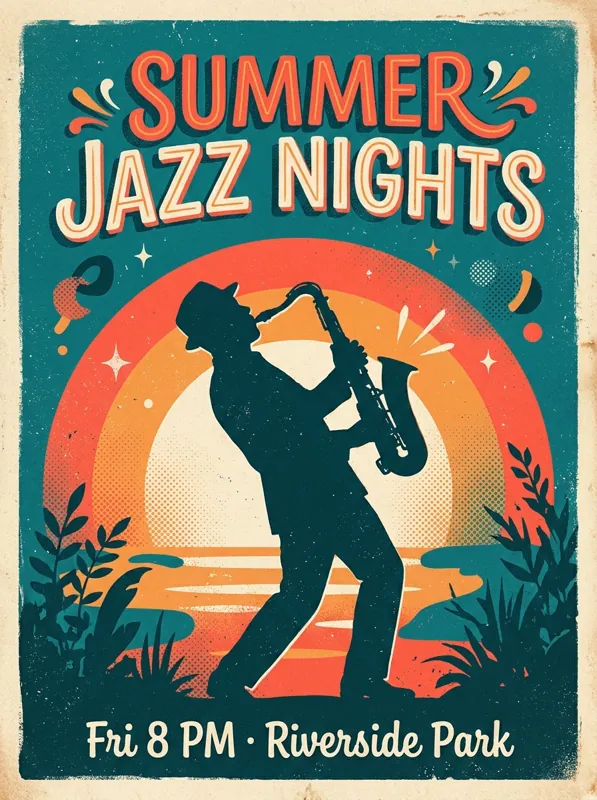
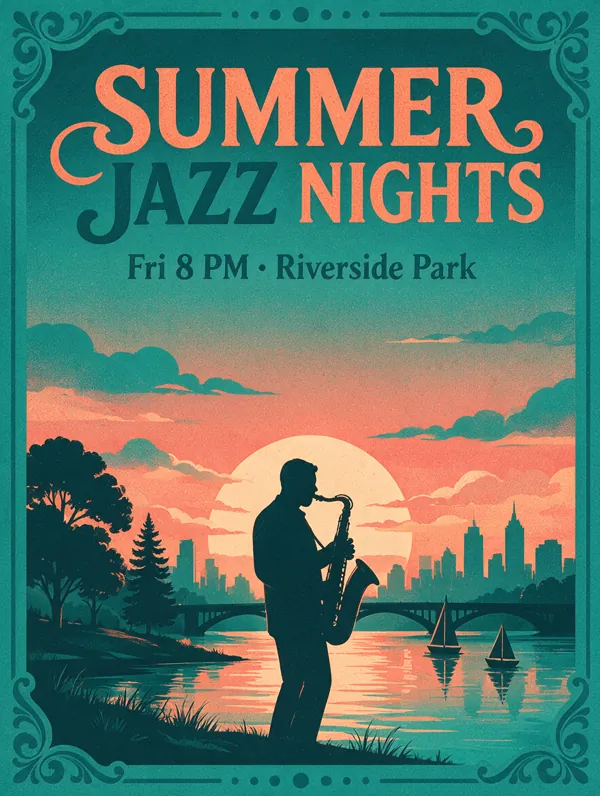
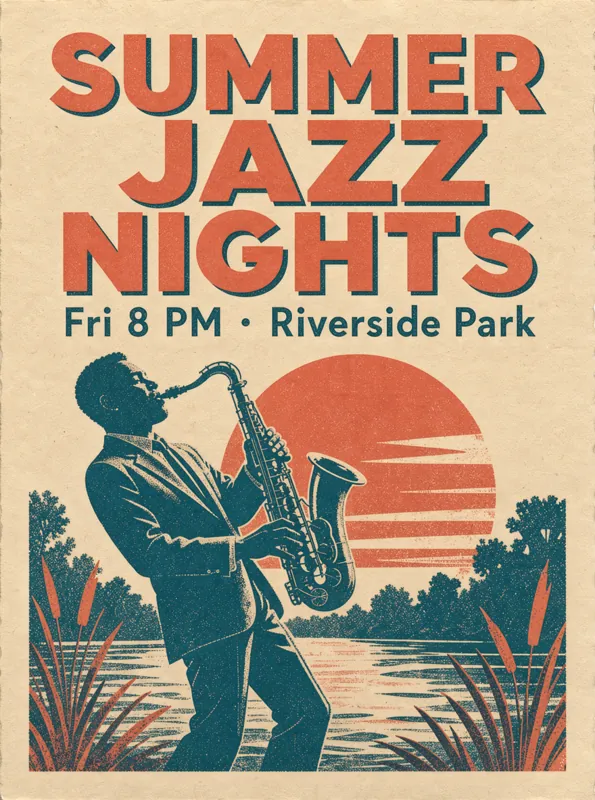
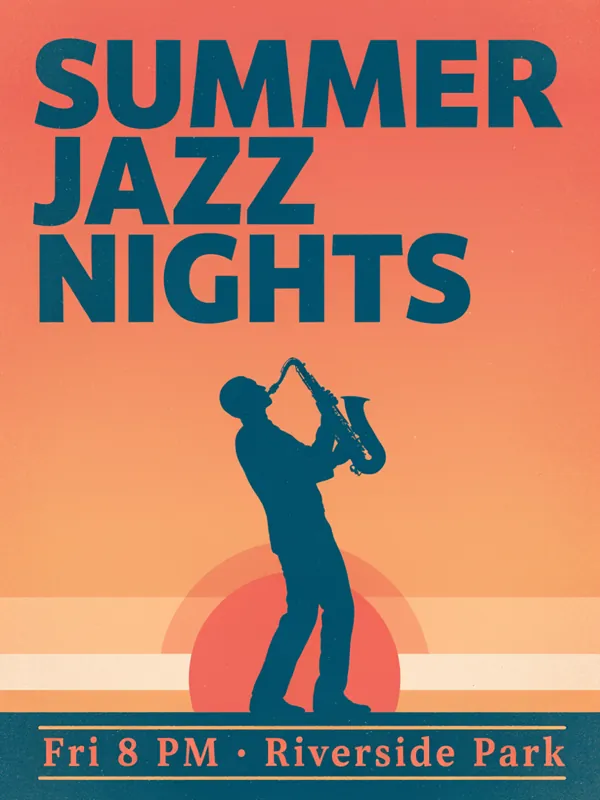
Poster 6: SUMMER JAZZ NIGHTS / Fri 8 PM · Riverside Park
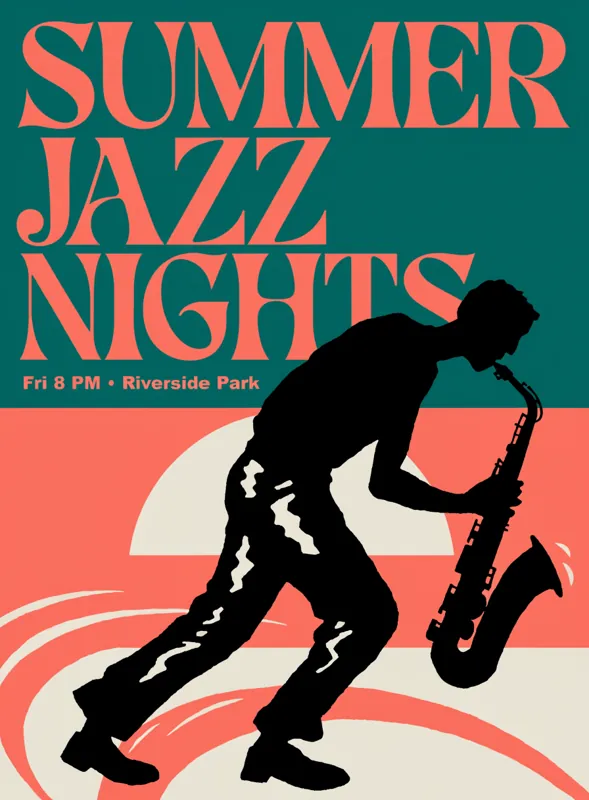
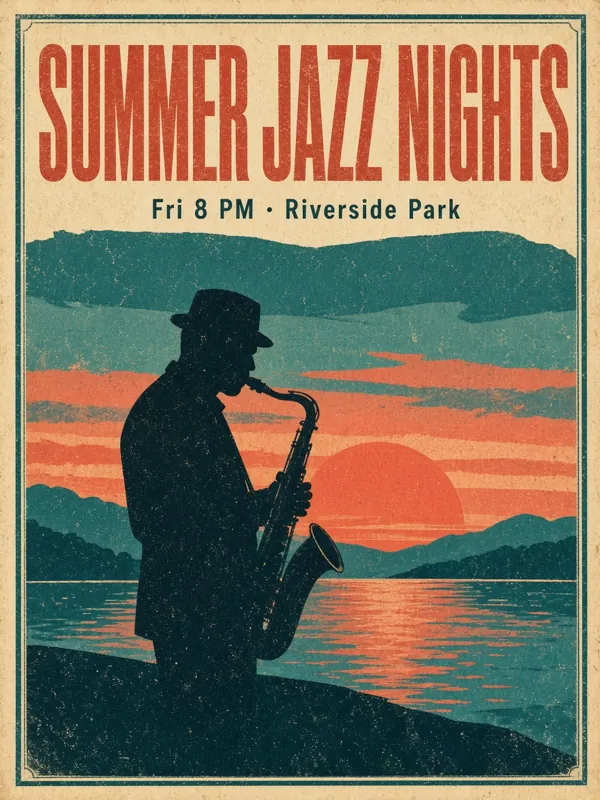
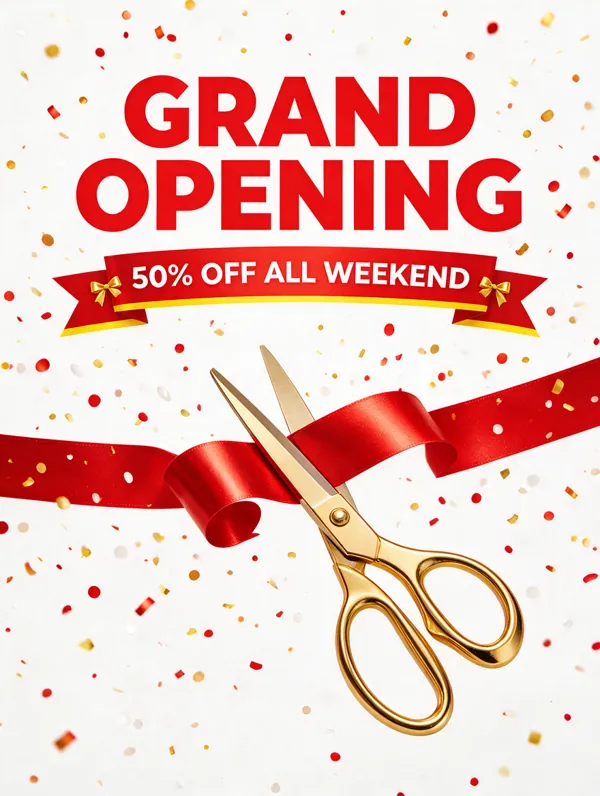
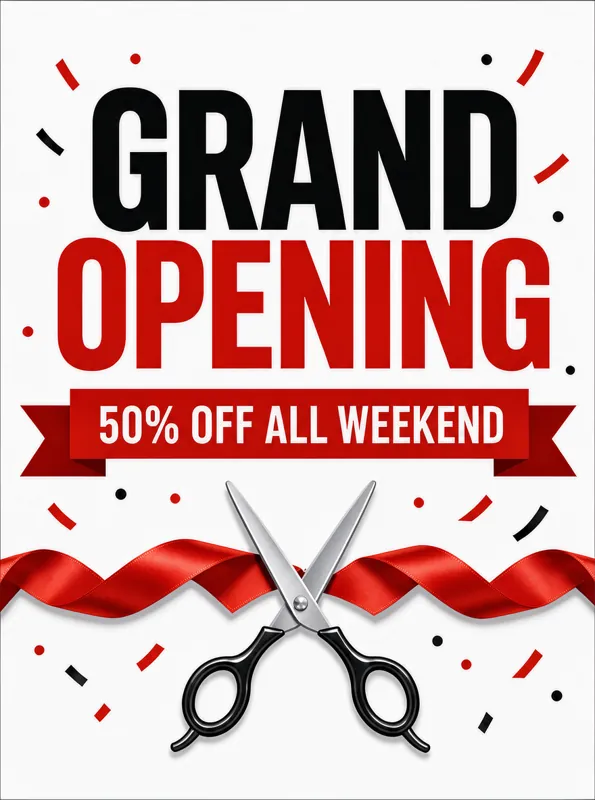
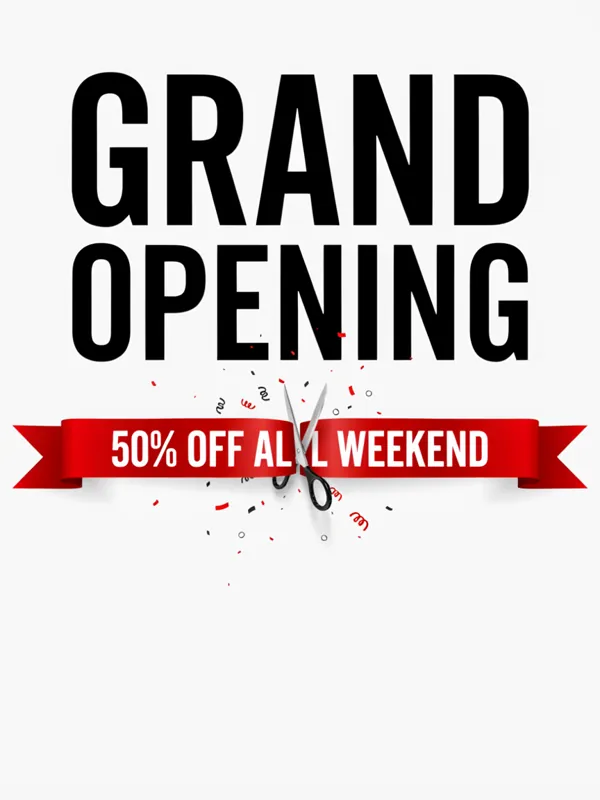
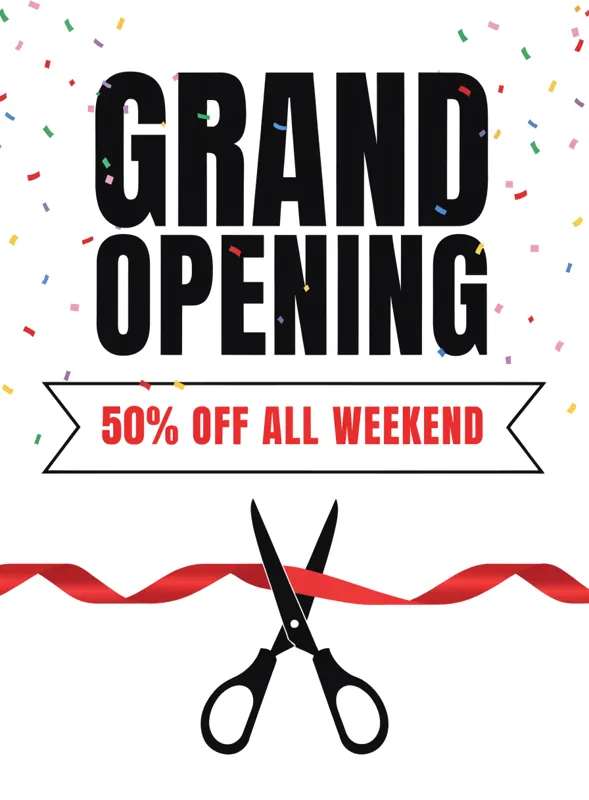
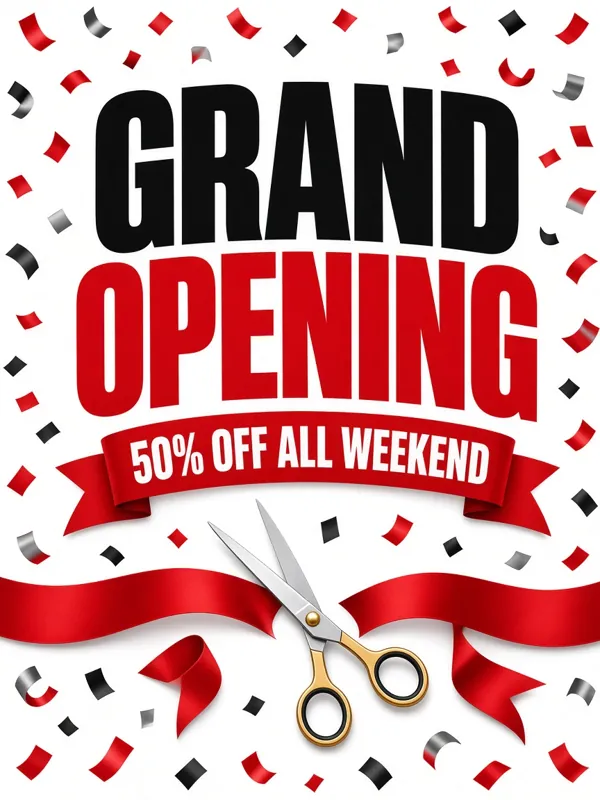
Poster 7: GRAND OPENING / 50% OFF ALL WEEKEND
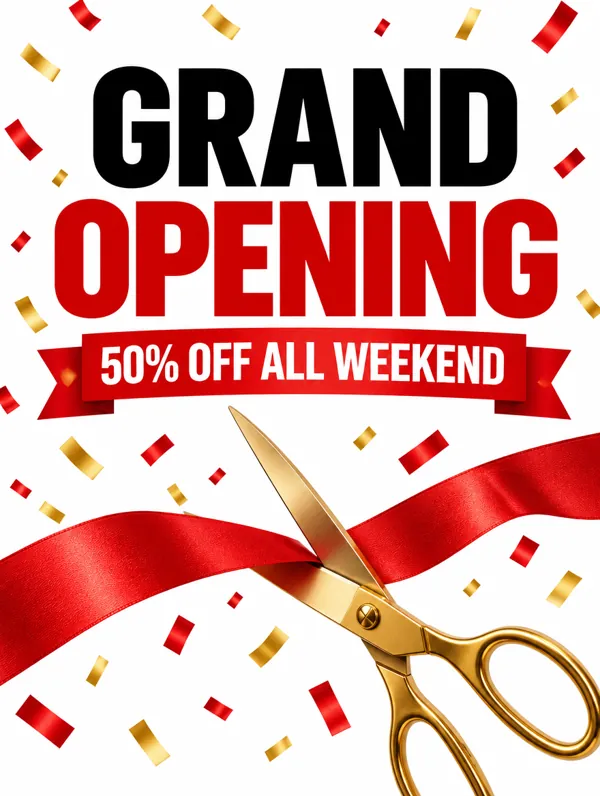
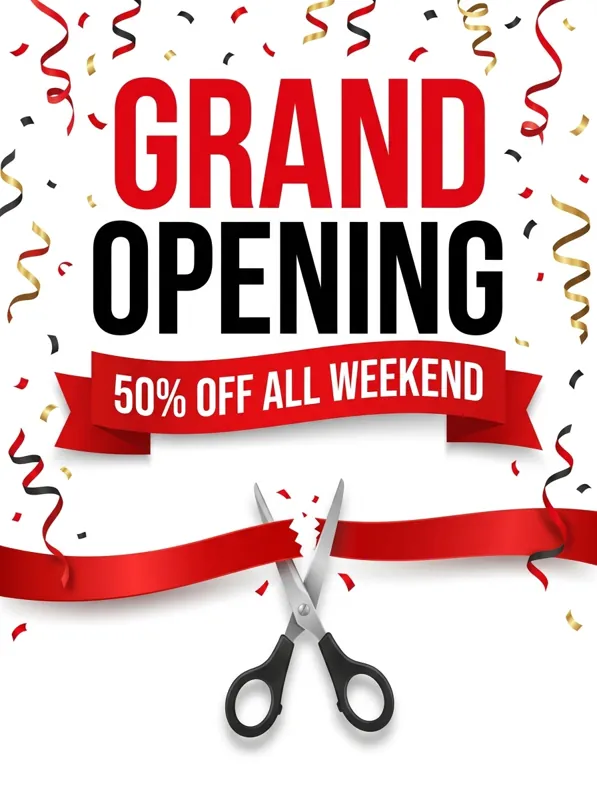
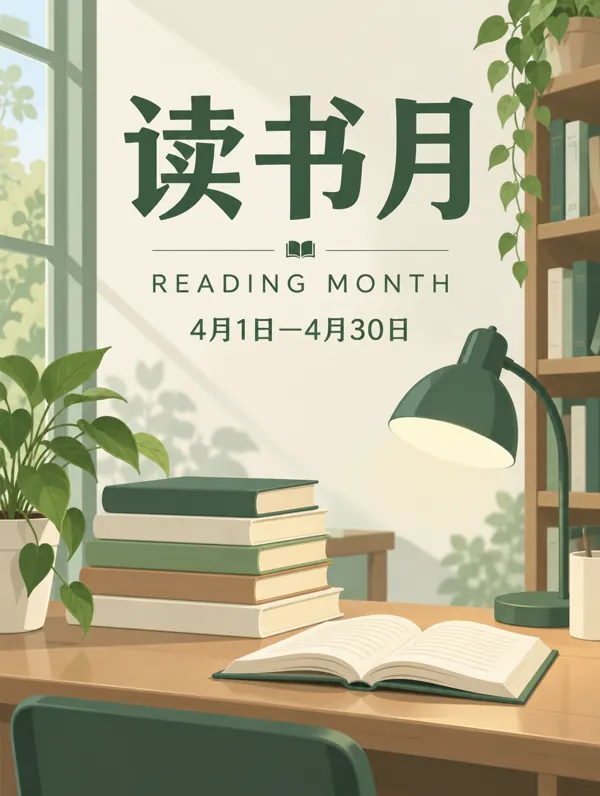
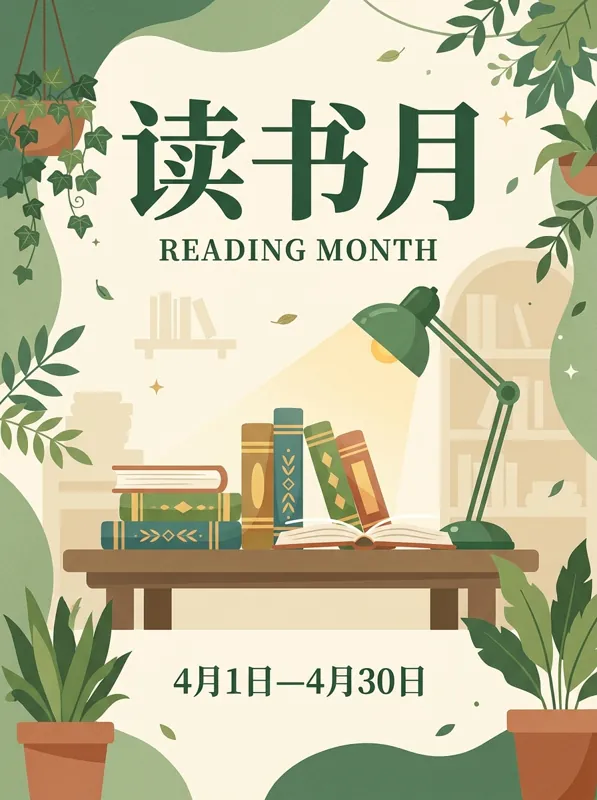
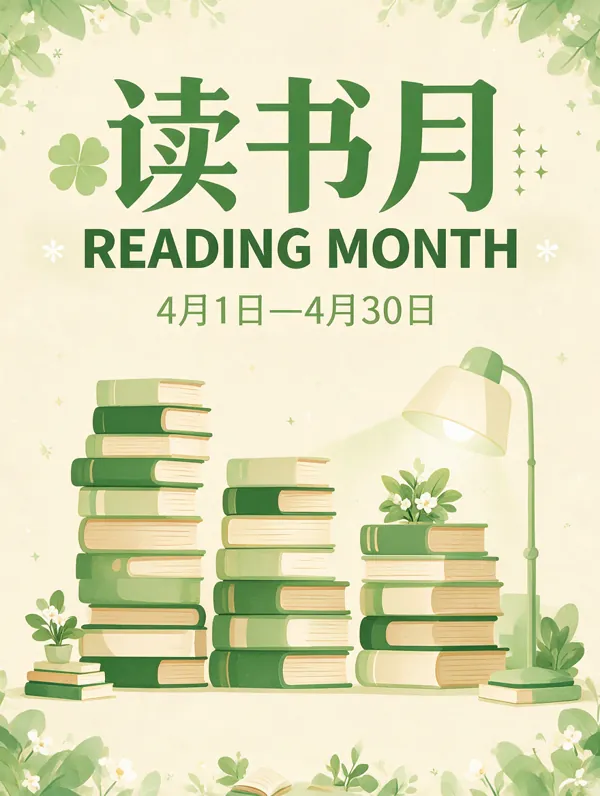
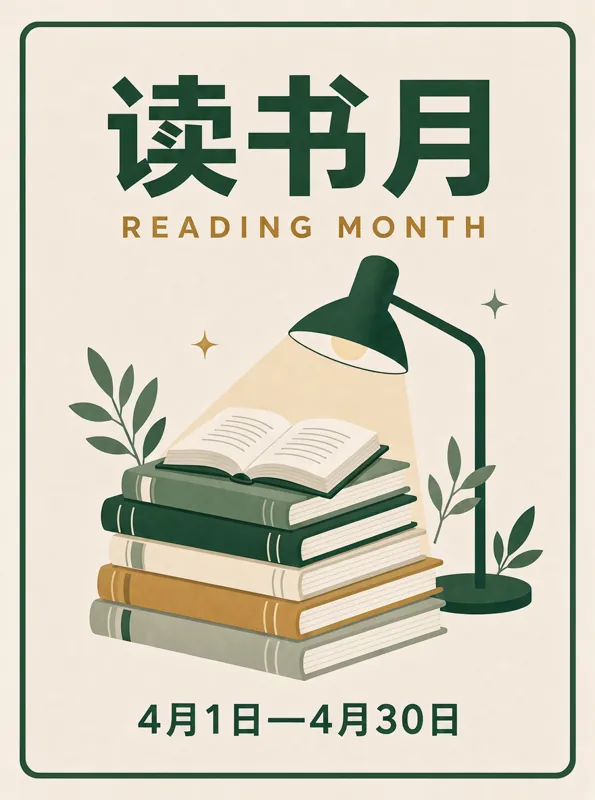
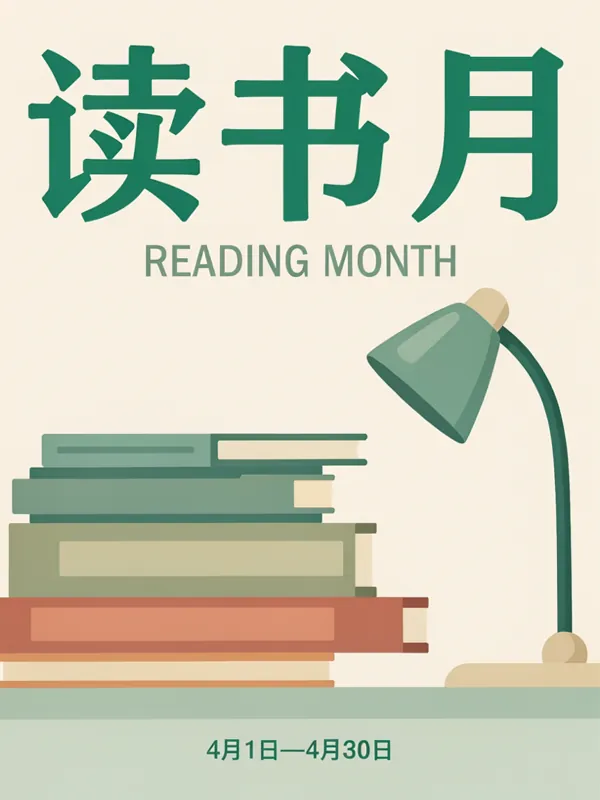
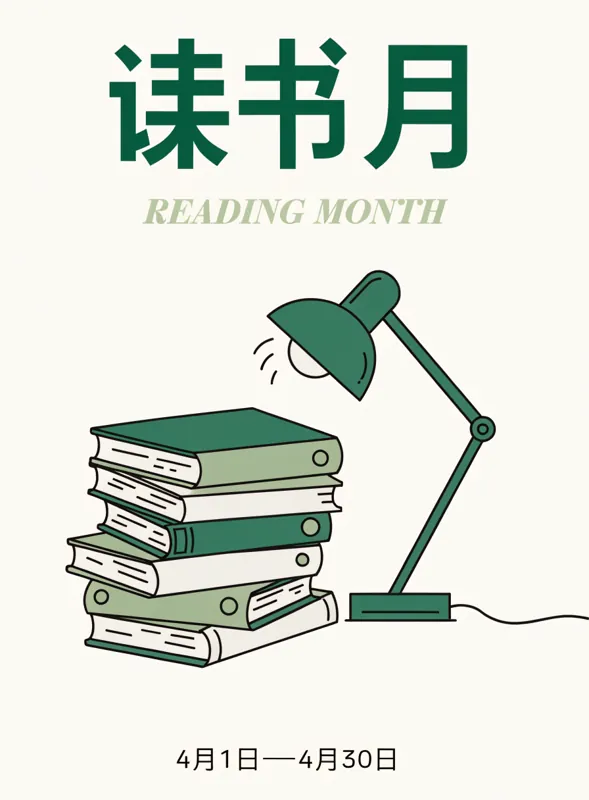
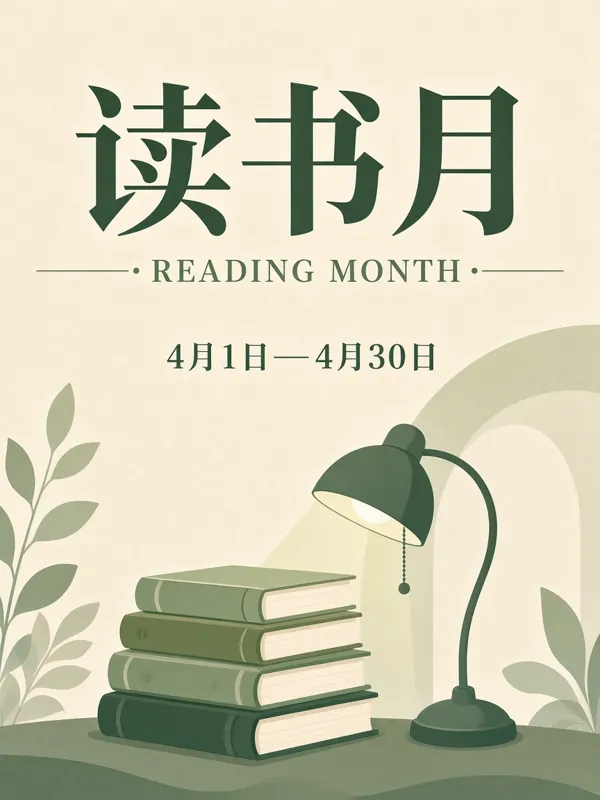
Poster 8: 读书月 / READING MONTH / 4月1日—4月30日
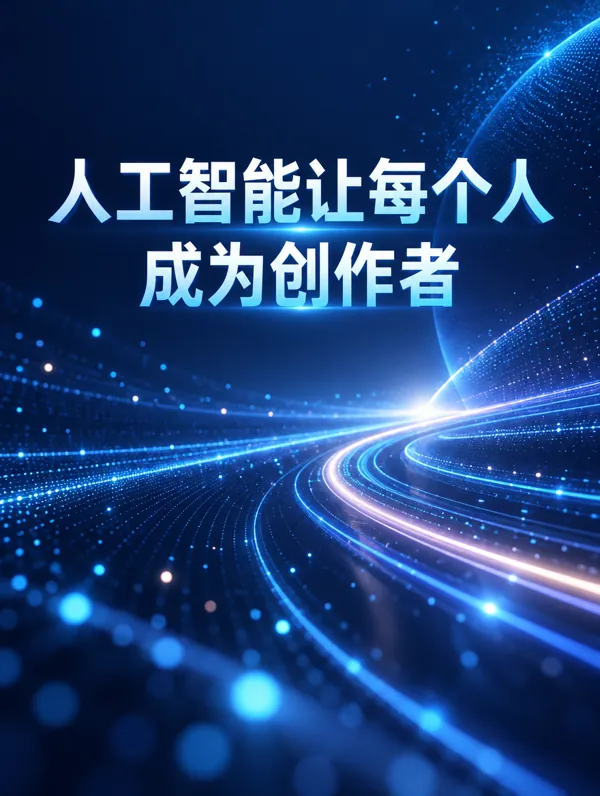
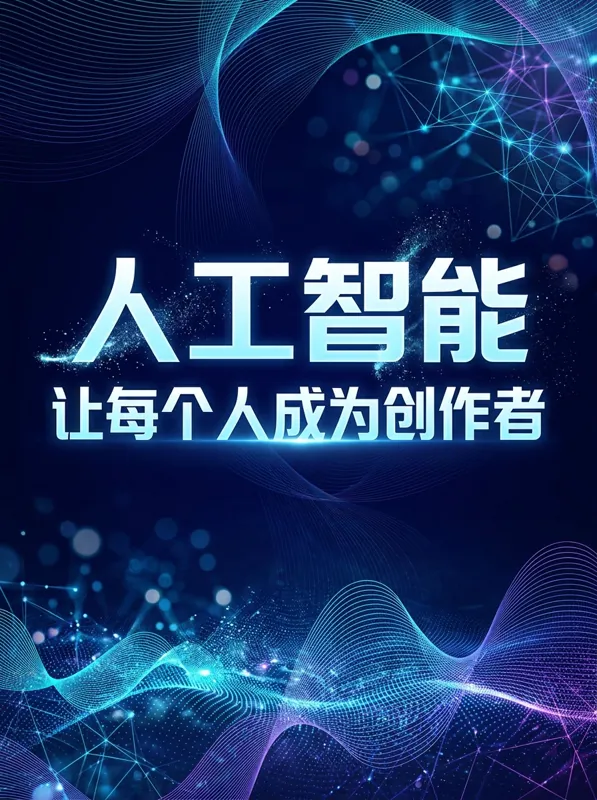
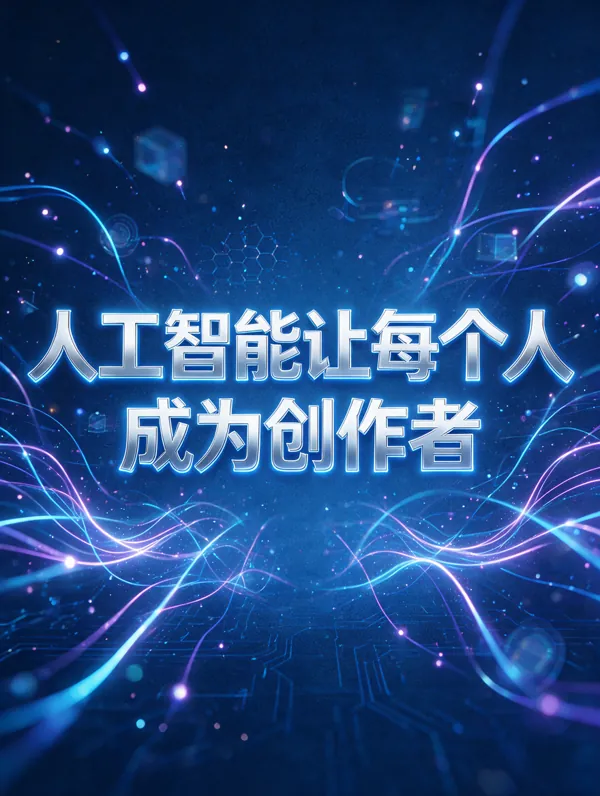
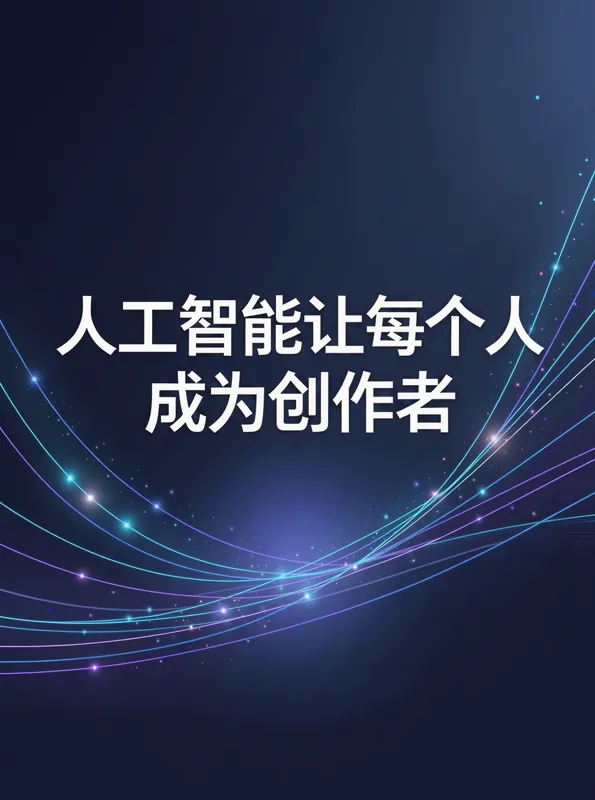
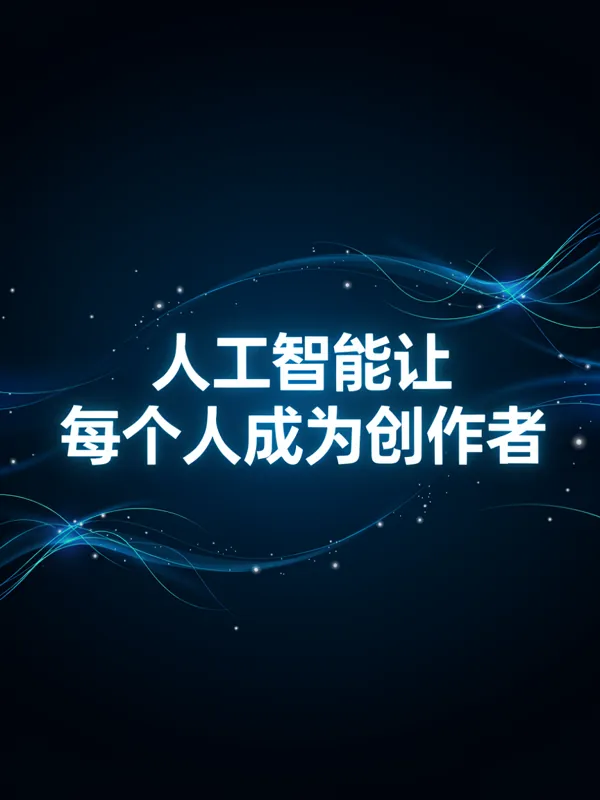
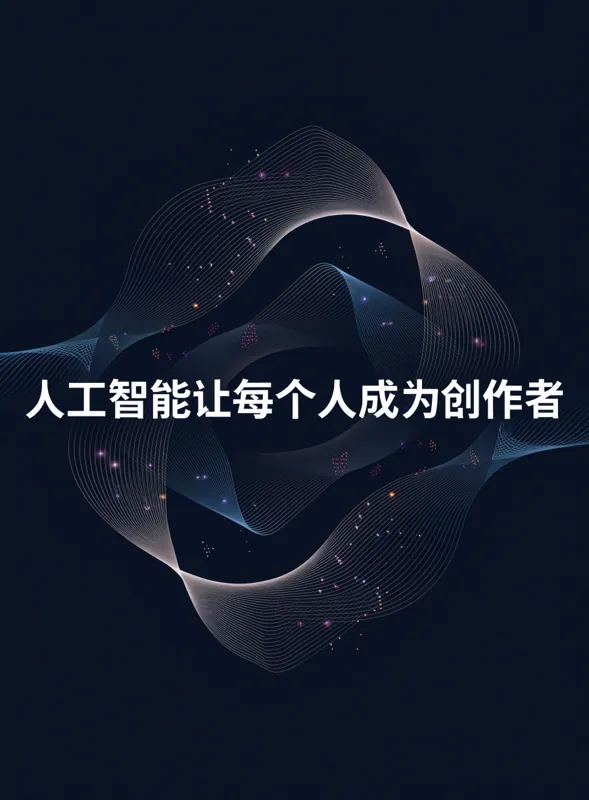
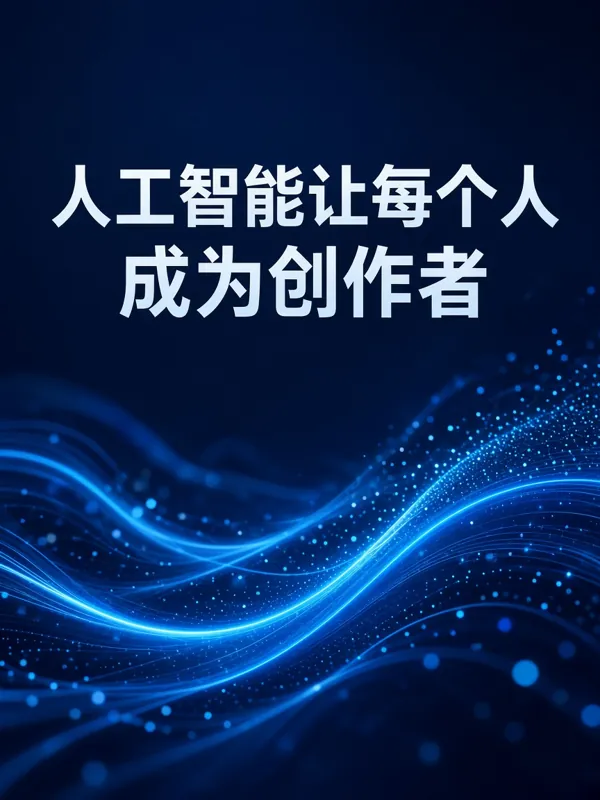
Poster 9: 人工智能让每个人成为创作者
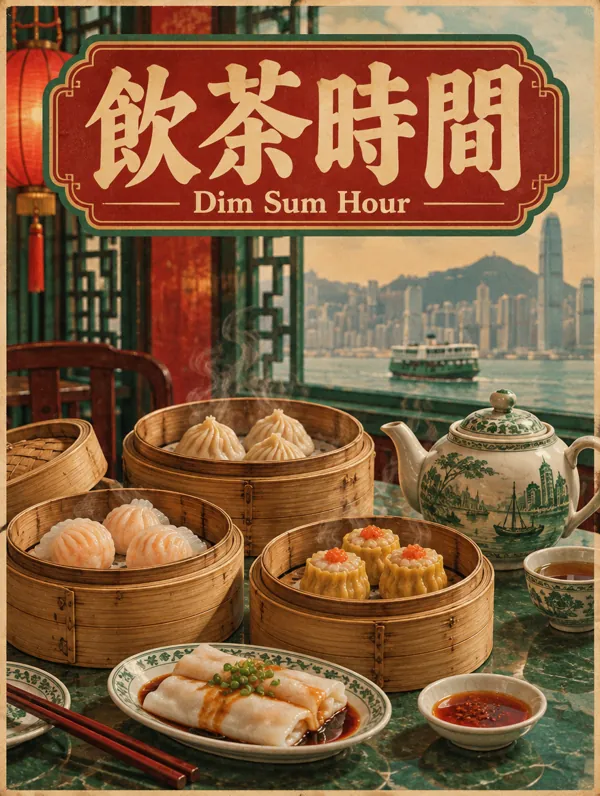
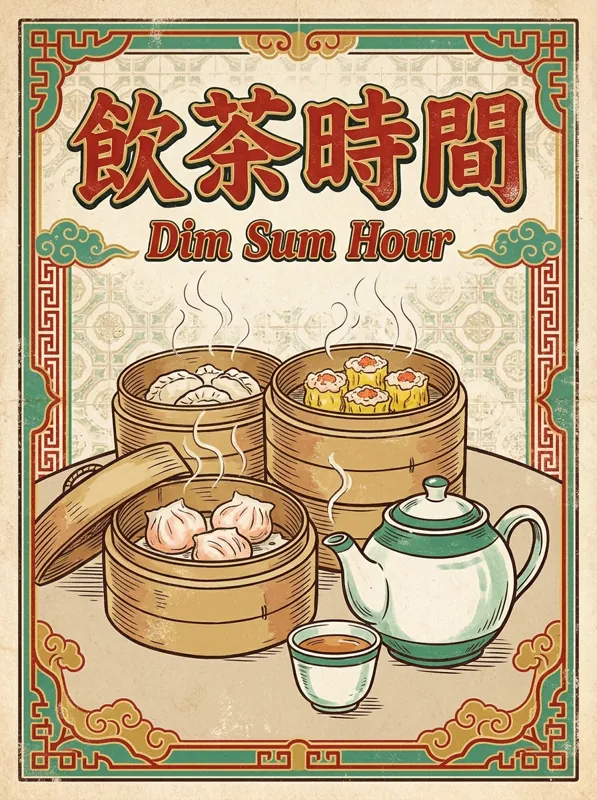
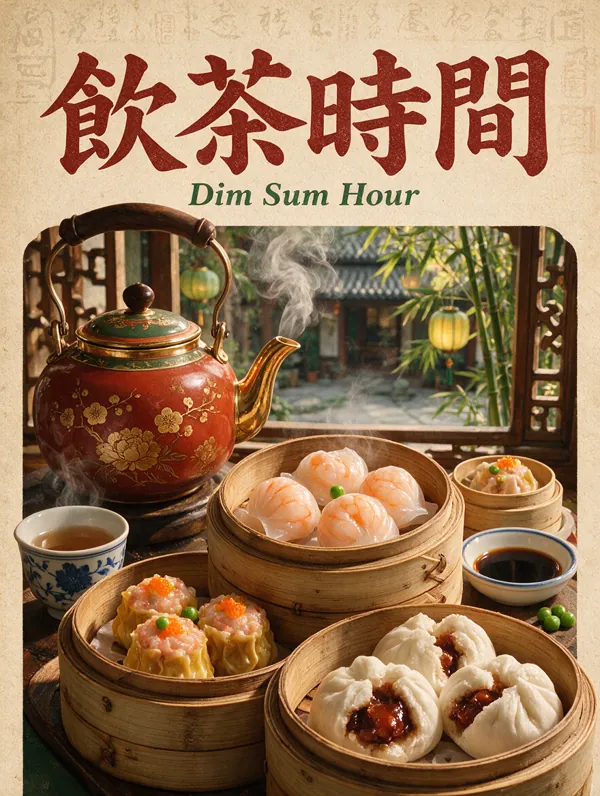
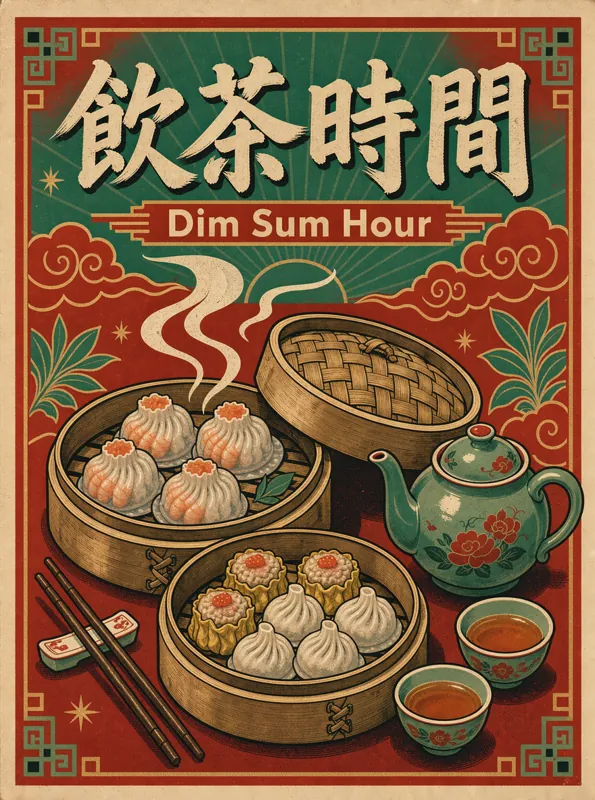
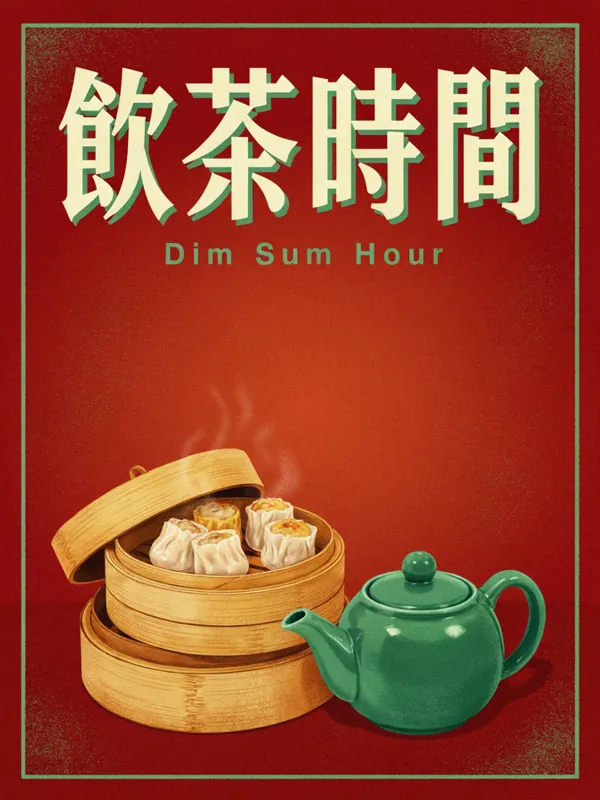
Poster 10: 飲茶時間 / Dim Sum Hour
How we tested
Ten poster briefs: three in Chinese only, two in English only, four mixing Chinese and English, and one in traditional Chinese. Headlines run from 3 to 13 Chinese characters, plus dates, prices and badges, 58 Chinese characters per model in total.
Every model got the identical prompt at a 3:4 ratio and about 1K resolution, using the settings listed in the table. We ran them all on Higgsfield on 31 Oct 2026, so the cost column is comparable. Each poster was checked character by character against the brief. Wrong characters, invented characters and missing words count as errors; a word that is right but partly covered is noted, not counted.
Then four people on our team graded all 70 posters for design and for fitting the brief, 1 to 10, without seeing which model made which. Each grader saw the posters in a different order. Because some people score higher than others across the board, we adjust each grader's scores to a shared scale before averaging, so only how they ranked the posters counts.
Midjourney V8.1 and Qwen-Image 3.0 are on our list but were not available on the platform we used; they join the next round. Our full methodology.
Questions people ask
Why do AI images get Chinese characters wrong?
Image models draw text as shapes, not spelled words. Chinese has thousands of characters, many with dense strokes, so a model can produce strokes that look plausible but form a wrong or non-existent character. In this round the errors were exactly that: 看 for 春, 钣 for 饭, and an invented character in place of 吃.
Which AI is best for Xiaohongshu cover images?
Covers are their own job, with short headlines and busy layouts. We test them separately in social covers and thumbnails.
Can I use these posters commercially?
It depends on each provider's terms and your plan. Most paid plans allow commercial use of what you generate, but the terms differ, so check the current terms before using an image in an ad.
How long can the text be before models fail?
All seven models handled our longest headline, 13 characters across two lines, without an error. The three errors came on 4- and 6-character headlines, so length alone did not predict failure in this round.
Related
Best AI for product photos · GPT Image 2.5 vs Seedream 5.0 Pro · All image jobs